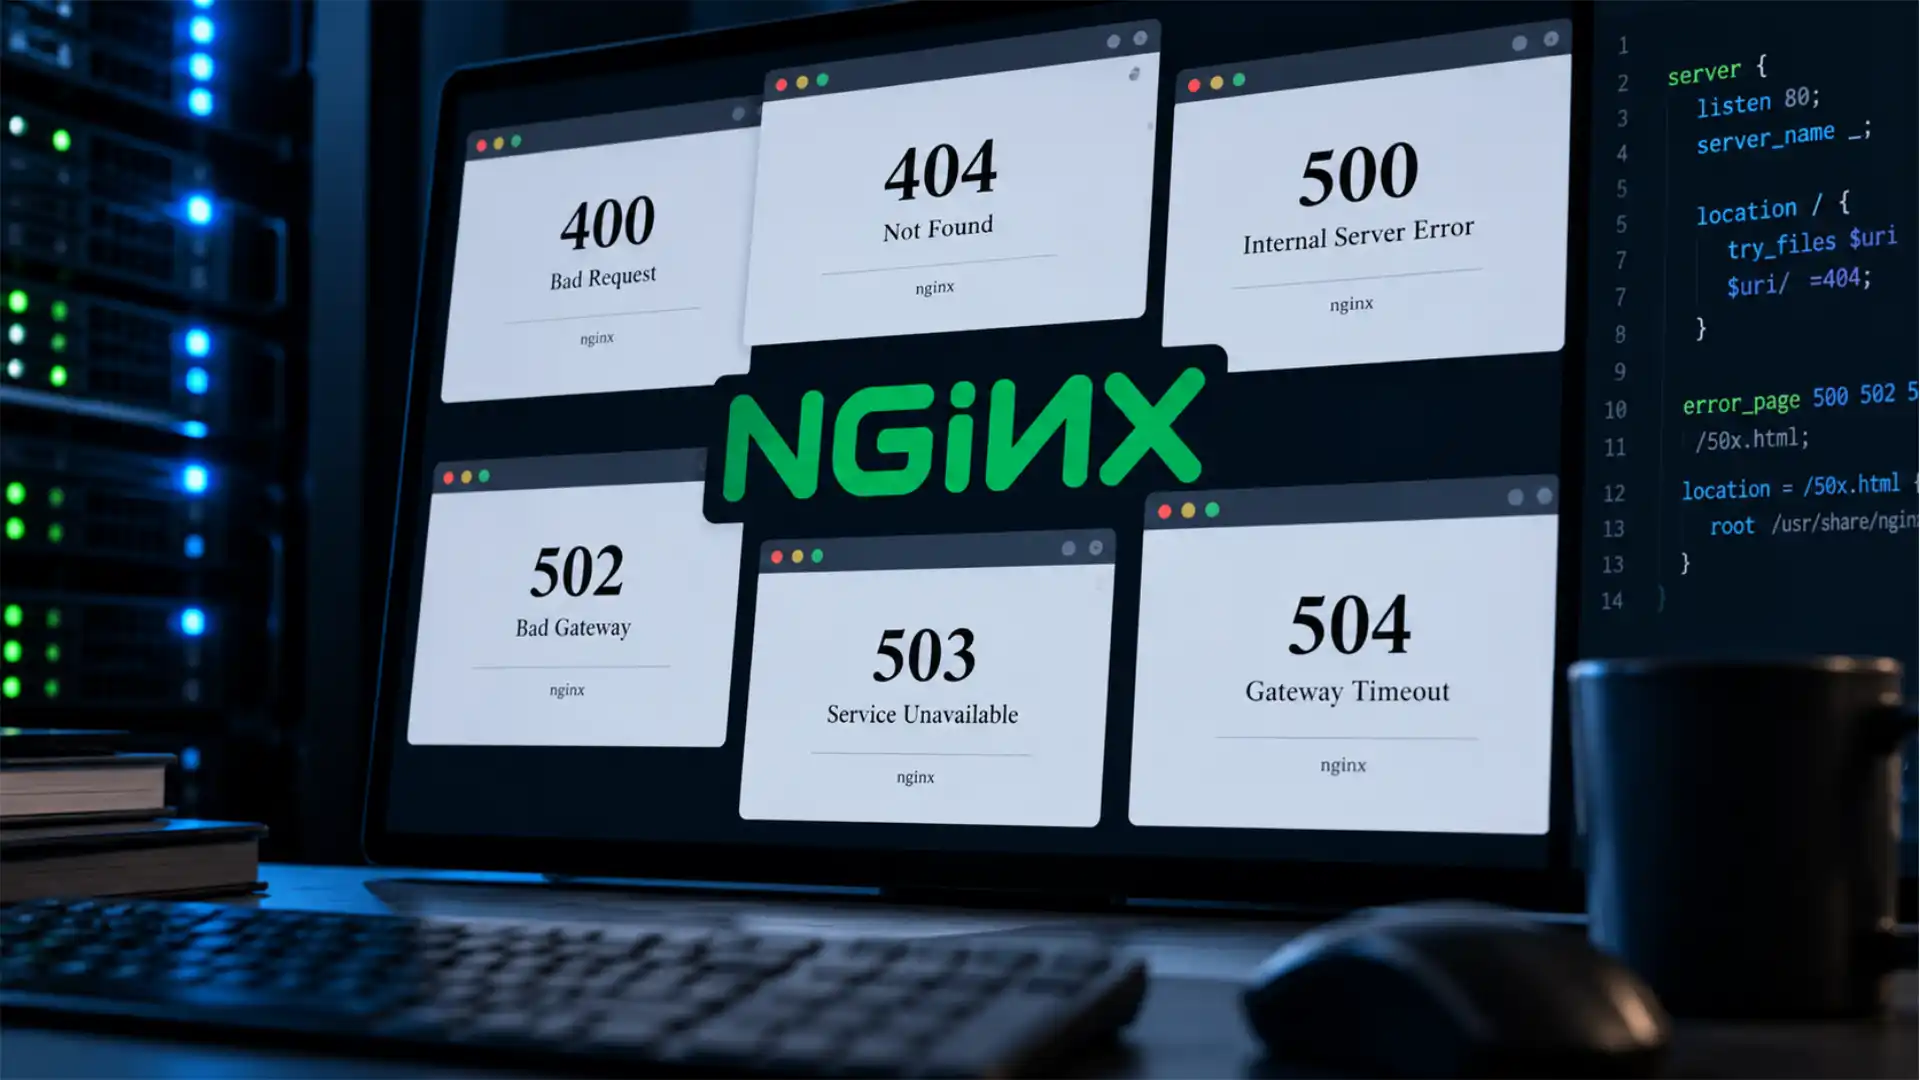
Every NGINX error page looks the same: a plain white background, a three-digit number, a short phrase, and the word “nginx” printed underneath in small type. That uniformity is the first thing that misleads people trying to fix a broken site. A 404 and a 502 come from completely different parts of the request path, get caused by completely different mistakes, and get fixed with completely different commands — but the page itself gives almost no hint of which problem you’re actually looking at.
Table of Contents
Why NGINX error pages look identical but never mean the same thing
An HTTP status code tells you which layer failed, not what broke inside it. A 404 says NGINX could not match the request to a file, a route, or a fallback. A 403 says NGINX found something but refused to hand it over. A 500 says something crashed while generating the response. A 502 says NGINX asked another process for an answer and got garbage back, or nothing at all. A 504 says NGINX asked and waited, and the answer never arrived in time. Four different failures, four different fixes, one identical-looking error page.
This matters because most people’s first instinct when a site breaks is to restart NGINX. Sometimes that works, by accident, because a stuck worker process gets cleared. Most of the time it does nothing, because the fault sits somewhere NGINX never touches — a crashed PHP-FPM pool, a full disk on the database server, a certificate that expired six hours ago, a cookie that grew past a buffer limit during a Black Friday checkout flow. Restarting the front door does not fix a broken kitchen.
This article works through the full set of server errors a site running behind NGINX can produce: what each status code means technically, what specific misconfiguration or failure produces it in practice, which log line confirms the diagnosis, and which directive or command actually resolves it. It covers the codes everyone recognizes — 404, 500, 502, 503, 504 — and the ones almost nobody can name from memory, including 495, 496, 497, and 431, each of which shows up in production far more often than its obscurity suggests.
The organizing idea is simple: every error NGINX produces falls into one of five status classes, and the class alone eliminates most of the wrong guesses. A 4xx code means the request itself was the problem — malformed, too large, unauthenticated, pointed at something that doesn’t exist. A 5xx code means the request was fine and the server side failed to handle it. Confusing the two wastes the most debugging time of any single mistake in this entire subject: engineers who treat a 429 like a server crash, or a 502 like a client mistake, end up tuning the wrong configuration file for hours.
The rest of this piece goes error by error, in roughly the order you’re likely to meet them in a production incident, with the exact NGINX directive, log signature, and fix for each one.
How an HTTP status code actually gets chosen
NGINX does not invent status codes on the spot. It runs every request through a fixed sequence of phases — rewrite, access control, and content generation — and a status code gets attached at whichever phase the request fails, or at the end if it succeeds. Understanding that sequence explains why the same URL can return three different codes depending on what changed upstream, on disk, or in a configuration file.
The rewrite phase applies rewrite rules and internal redirects before NGINX decides how to serve anything. A broken rewrite rule can send a perfectly valid request into a dead end that produces a 404 even though the file it was originally asking for exists. The access phase evaluates allow, deny, authentication directives, and client-certificate verification; a request that fails here gets a 403, 401, or one of the SSL-specific codes before NGINX ever looks at the file system. The content phase is where most people assume all the action happens: NGINX either serves a static file through root or alias, hands the request to a FastCGI process through fastcgi_pass, forwards it to another server through proxy_pass, or returns a scripted response through return. Each of those four paths has its own independent set of failure modes, which is why “NGINX is throwing errors” is never a complete diagnosis — you have to know which path the failing request took.
A request that reaches a proxied backend hands control to a process NGINX does not own. From that point, the status code NGINX returns to the client is usually just relaying what the backend said — unless proxy_intercept_errors or fastcgi_intercept_errors is turned on, in which case NGINX substitutes its own error page for specific backend status codes. That single setting is responsible for a surprising share of “why does my custom error page not show up” tickets: without it, NGINX passes the backend’s raw error response straight through, custom error_page directives and all being ignored for that particular status.
The status code a client sees is therefore the output of a small state machine, not a direct report of what physically happened on the server. A database timeout three layers deep can surface as a 504 at the edge, a 502 if the immediate backend crashes instead of hanging, or a 500 if the application catches the exception and returns its own generic error page. Reading only the number the browser shows is like diagnosing a car problem from the dashboard warning light alone — useful as a starting point, useless as a full diagnosis. The NGINX error log, not the browser tab, is where the actual diagnosis happens, and the next two sections of this piece establish exactly how to read it.
The five status classes and where NGINX sits inside each one
HTTP status codes are grouped into five classes by their first digit, a structure formalized in RFC 9110 and maintained as the authoritative IANA HTTP Status Code Registry. 1xx codes are informational and rarely surface in ordinary debugging. 2xx codes mean success. 3xx codes mean redirection. 4xx codes mean the client’s request was the problem. 5xx codes mean the server failed to handle a request that was, as far as the server could tell, valid.
That single distinction — 4xx versus 5xx — is the fastest triage step available and the one most frequently skipped under pressure. A 4xx error means nothing is broken on your server in the sense of a crash or an outage; it means NGINX is correctly refusing or rejecting a specific request. A flood of 404s usually means bad links, a broken deployment that removed routes, or bots probing for vulnerable paths — not a server failure. A flood of 403s usually means a permissions or access-control change, intentional or not. Neither pattern indicates the server is down. A 5xx error means the opposite: the server accepted the premise of the request and then failed to deliver a response, which is the pattern that correlates with actual outages, actual revenue loss, and actual pages going out to on-call engineers.
NGINX itself generates codes from both classes, and it is worth being precise about which ones originate at the NGINX layer versus which ones NGINX merely relays from somewhere else. NGINX generates 400, 403, 404, 405, 413, 414, 431, 495, 496, 497, and — when its own resource limits are hit — 500 and 503 directly, without any backend involved. It generates 502 and 504 specifically in its role as a proxy, when it fails to get a valid or timely response from an upstream. It relays whatever a backend sends for everything else, including most instances of a plain 500 from a PHP or Node.js application, unless proxy_intercept_errors on; or fastcgi_intercept_errors on; tells it to substitute its own page instead.
Codes not in the IANA registry should not appear in production traffic, and a small set of unregistered or borderline codes do show up around NGINX deployments anyway: 418, the April Fools’ “I’m a teapot” from RFC 2324 that a small number of servers implement as a joke; and the load-balancer-and-CDN-specific codes that Cloudflare and similar edge providers layer on top of the standard set (520 through 530), which are not NGINX codes at all but frequently get confused with them because they appear in the same 5xx range and often sit directly in front of an NGINX origin.
The table below groups every status code this article covers by class, which is the single fastest lookup when a specific number shows up in a log line and you need to know, in one glance, whose fault it probably is.
HTTP status codes NGINX generates or relays, grouped by class
| Class | Codes covered here | What the class means | Typical NGINX role |
|---|---|---|---|
| 4xx client error | 400, 401, 403, 404, 405, 413, 414, 429, 431 | The request itself is malformed, unauthorized, oversized, or points at nothing | Generated directly by NGINX during rewrite, access, or content phases |
| 4xx / SSL-specific | 495, 496, 497 | The TLS handshake or client-certificate verification failed or was skipped | Generated directly by NGINX’s SSL module |
| 5xx server error | 500, 503 | An unexpected failure or a temporary capacity limit | Generated by NGINX itself or relayed from a backend |
| 5xx / proxy-specific | 502, 504 | NGINX could not get a valid or timely response from an upstream | Generated only when NGINX is acting as a proxy or gateway |
The table is a lookup, not a diagnosis. Knowing that 413 is a 4xx tells you the client sent something too large; it doesn’t tell you which directive to change or which log line to search for, which is what the rest of this article works through code by code.
Reading the NGINX error log like a diagnostic instrument
Every fix in this article assumes you can read the NGINX error log, because the log line is almost always more specific than the status code the browser shows. The default location is /var/log/nginx/error.log on most distributions, though some setups — particularly containerized ones — redirect it to standard error, in which case docker logs or journalctl -u nginx is where it actually lives. If the file is empty or missing, NGINX is very likely writing to a different destination than you expect, not that it has stopped logging entirely.
The error_log directive controls both the destination and the verbosity level, and the level matters enormously for debugging. The default error level captures genuine problems but misses a lot of context that would explain them. Setting the level to warn or notice temporarily during an investigation surfaces detail — retry attempts, buffer warnings, connection state changes — that the default level suppresses. debug level is the most verbose and requires NGINX to be compiled with --with-debug, but it is the only level that shows the exact sequence of internal decisions NGINX made for a single request, which is occasionally the only way to understand a rewrite-rule interaction or a try_files chain that isn’t behaving as expected.
Specific log-line signatures map directly to specific root causes, and learning to recognize them by sight cuts diagnosis time from hours to minutes. connect() failed (111: Connection refused) while connecting to upstream means nothing is listening on the port or socket NGINX tried to reach — the backend process is not running. upstream timed out (110: Connection timed out) while reading response header from upstream means the backend accepted the connection but never produced a response within the configured window. No such file or directory in the context of a static file request maps directly to a 404, while Permission denied on the same kind of request maps to a 403 — those two OS-level error strings are often the fastest way to tell a routing problem from a filesystem-permissions problem, since both can otherwise look identical from the browser. client intended to send too large body is the 413 signature. directory index of "..." is forbidden is the specific 403 variant caused by a missing index file with autoindex left off.
The suffix after “upstream timed out” tells you which of three phases failed, and that distinction changes the fix entirely. NGINX’s proxy module tracks connecting, sending, and reading as three separate timeout phases, each governed by its own directive — proxy_connect_timeout, proxy_send_timeout, and proxy_read_timeout respectively (with fastcgi_connect_timeout, fastcgi_send_timeout, and fastcgi_read_timeout as the FastCGI equivalents). A timeout during the connecting phase means the backend is unreachable or overloaded at the TCP level. A timeout during the reading phase — by far the most common of the three in production — means the connection succeeded but the backend took too long to finish its work. Raising proxy_connect_timeout when the real problem is a slow database query accomplishes nothing; the fix has to target the phase the log line actually names.
Access logs complement error logs by carrying timing data the error log doesn’t include. The next section covers exactly which access-log fields matter and how to configure NGINX to record them, because a default access log format captures the status code and the URL but nothing about how long the backend took to answer — the single most useful number for telling a slow-backend 504 apart from a dead-backend 502.
The access log fields that separate an NGINX fault from a backend fault
The default NGINX access log format — combined — records the client IP, the request line, the status code, the response size, the referrer, and the user agent. It does not record how long anything took, which means a default-configured access log cannot distinguish a request that failed instantly from one that hung for fifty-nine seconds before timing out. Adding timing variables to a custom log_format closes that gap and turns the access log from a record of what happened into a record of why.
The variables worth adding are $request_time, which measures the full time NGINX spent on the request from the first byte received to the last byte sent to the client, and the upstream-specific set: $upstream_connect_time, $upstream_header_time, and $upstream_response_time, which measure the time to establish a connection to the backend, the time to receive the first byte of the response headers, and the total time to receive the full upstream response, respectively. A custom format that includes all four looks like this:
log_format detailed '$remote_addr - $remote_user [$time_local] '
                     '"$request" $status $body_bytes_sent '
                     'rt=$request_time uct="$upstream_connect_time" '
                     'uht="$upstream_header_time" urt="$upstream_response_time"';
The gap between $request_time and $upstream_response_time is one of the most useful single numbers in NGINX troubleshooting. When the two are nearly equal, NGINX is spending its time waiting on the backend, and the fix belongs in the application or database layer. When $request_time is significantly larger than $upstream_response_time — sometimes by an order of magnitude, with the backend logging a response in under fifty milliseconds while the client-facing request time runs into full seconds — the delay is happening inside NGINX itself, most often because a large response is overflowing the in-memory proxy_buffers and spilling to a temporary file on disk, a process that happens silently and only shows up at the debug log level.
$upstream_status is worth adding separately from the client-facing $status, because they diverge exactly in the cases that matter most: when proxy_intercept_errors is on and NGINX substitutes its own error page for a backend failure, the access log’s $status field shows what NGINX sent the client while $upstream_status shows what the backend actually returned — and comparing the two tells you immediately whether a given 500 originated in your application or in NGINX’s own handling of it.
A comma-separated value in $upstream_response_time — something like 0.002, 0.004, 30.001 — is the signature of a retry cascade, where NGINX attempted the same request against multiple upstream servers in sequence because proxy_next_upstream is configured to retry on error or timeout. That single log line indicates NGINX quietly tried and failed against more than one backend before finally giving up, which is a very different situation from a single clean timeout and usually points at a broader upstream health problem rather than one bad server.
With the error log and a timing-aware access log both in place, the rest of this article works through each status code NGINX can produce, starting with the smallest and least dramatic: the codes that mean the request itself, not the server, was the problem.
400 Bad request and the header block NGINX refuses to parse
A 400 response means NGINX could not parse the request as valid HTTP before it ever got to decide what to do with it. This sits earlier in the pipeline than almost every other error in this article — earlier than routing, earlier than access control, earlier than any backend involvement. NGINX generates a 400 for malformed request lines, invalid header syntax, and a small set of protocol-level violations that have nothing to do with your application logic at all.
The most common trigger in real production traffic is not a malformed request line — modern browsers essentially never send one — but an oversized header field that exceeds a configured buffer, most often the Cookie header. The rule that trips up almost everyone the first time they meet this error: the buffer count in large_client_header_buffers is not additive. The directive large_client_header_buffers 4 8k; — the default — does not mean NGINX will accept a combined 32 kilobytes of headers. It means NGINX allocates four buffers of 8 kilobytes each, and a single header line has to fit entirely within one buffer. A Cookie header that has grown past 8 kilobytes because of accumulated tracking cookies, session tokens, and a WordPress or WooCommerce session cookie stacking on top of everything else will fail even if the combined header block is well under the theoretical 32-kilobyte ceiling, because no single buffer can hold it.
The fix is to raise the size of each buffer, not the count:
large_client_header_buffers 4 16k;
This doubles the space available for any single header line. Raising the count instead — to 8 8k, for instance — does nothing for the one-oversized-cookie problem, because the constraint that actually failed was per-line, not aggregate. The permanent fix is almost always to reduce what the application is putting into cookies in the first place — moving from client-side, cookie-stored session data to a server-side session store referenced by a small session-ID cookie eliminates the failure mode entirely rather than just raising the ceiling it runs into.
A second, less common 400 trigger is a proxy chain where an intermediate layer — a CDN, a load balancer, or another NGINX instance sitting in front of the one you’re debugging — has different buffer settings than the instance actually serving the error. This produces an intermittent 400 that is unusually hard to track down, because the failure depends on which specific header content happens to be present on a given request and which layer in the chain first hits its limit. Checking every hop’s configuration, not just the NGINX instance closest to the application, is the only reliable way to close this out; fixing the buffer size on one layer while another stays at its default just moves the failure point rather than removing it.
A third trigger worth knowing by its distinct error message is 400 Bad Request: too many Host headers, which appears specifically when a proxy_set_header Host directive gets duplicated across an included configuration snippet and the main server block, resulting in the same header being sent twice. The fix is structural: consolidate the Host header assignment into a single location rather than setting it redundantly at multiple configuration levels.
Distinguishing a 400 generated directly by NGINX from a 400 relayed from a backend application matters for where you look next. NGINX’s own 400 responses happen before any proxy_pass or fastcgi_pass directive runs, so they never touch application logs at all — if your application’s own logging shows nothing for a request the client insists they made, and NGINX’s error log shows a header-related rejection, the backend was never involved and no amount of application debugging will find the cause.
Request header or cookie too large and the large_client_header_buffers fix
The specific 400 variant that deserves its own treatment is the one with the message “Request Header Or Cookie Too Large,” because it is common enough on any site that accumulates session state in cookies to warrant a dedicated diagnostic workflow rather than a generic buffer-size bump.
Measure before you configure. The fastest way to confirm the diagnosis is to open browser developer tools, go to the Network tab, reload the failing page, and inspect the raw byte length of the Cookie header under Request Headers for the failing domain. A quicker confirmation from the command line reproduces the exact failure with curl, sending a deliberately oversized Cookie header and checking for an immediate 400 with no upstream response at all — confirming that NGINX rejected the request at the edge before the application ever saw it.
Once confirmed, the immediate fix at the NGINX layer is:
http {
    large_client_header_buffers 4 32k;
    ...
}
This can be applied at the http, server, or location context, with more specific contexts overriding broader ones. Setting it globally in http is the simplest approach for most sites; setting it only for specific locations that are known to need it — an authenticated dashboard area, for instance, versus a public marketing site that never sets large cookies — keeps the buffer size from being needlessly large everywhere.
The buffer increase is a legitimate fix for a legitimate, measured requirement — but it is treating the symptom, not the disease, when the underlying cookie is bloated rather than intentionally large. WordPress sets several baseline cookies on login. WooCommerce layers cart and session cookies on top for stores with complex product variation logic. Analytics and advertising scripts add their own tracking cookies. None of these individually approaches the default 8-kilobyte limit, but their combination on a single domain, accumulated across months of a user’s browsing session, regularly does. The durable fix is architectural: move session state to server-side storage — Redis, Memcached, or a database-backed session table — and reference it with a short opaque session identifier rather than storing the session payload itself in the cookie. Every major web framework supports this pattern natively or through a well-maintained plugin, and it removes the failure mode rather than just raising the ceiling the failure mode runs into.
A useful diagnostic habit: configure a custom 400 error page specifically so that users encountering this error see actionable guidance — “clear your cookies for this site” — rather than a bare NGINX default page that gives them no path forward:
error_page 400 /custom_400.html;
location = /custom_400.html {
    root /usr/share/nginx/html;
    internal;
}
This does not fix the underlying cause, but it converts a dead end into a one-click resolution for the affected user while the durable, application-level fix gets scheduled.
401 Unauthorized and the difference a WWW-Authenticate header makes
A 401 response means the server requires authentication and the request did not supply valid credentials. RFC 9110 requires that a 401 response include a WWW-Authenticate header describing at least one authentication scheme the server accepts — a requirement frequently ignored in custom application error handling, which produces a technically non-compliant 401 that browsers and API clients may not know how to act on correctly.
In NGINX terms, 401 is most commonly produced by HTTP Basic Authentication configured through auth_basic and auth_basic_user_file:
location /admin/ {
    auth_basic "Restricted area";
    auth_basic_user_file /etc/nginx/.htpasswd;
}
A request without an Authorization header, or with credentials that don’t match an entry in the specified htpasswd file, gets a 401 along with the correctly formatted WWW-Authenticate: Basic realm="Restricted area" header, which is what triggers a browser’s native login prompt. The most common operational failure here is not a configuration mistake in the directive itself but a stale or corrupted .htpasswd file — permissions set so the NGINX worker process cannot read it, or a password hash generated with an algorithm the installed NGINX build doesn’t support.
The practical distinction that separates 401 from 403 matters enough to repeat explicitly: 401 means the server doesn’t know who you are, and re-authenticating might fix it; 403 means the server does know who you are and has decided you’re not allowed regardless. Logging in again resolves a genuine 401. Logging in again does nothing for a 403, because the server already evaluated the identity and rejected the request on its merits. Conflating the two in support documentation or user-facing error pages sends users down a useless retry loop for a permissions problem that a password reset cannot touch.
401 responses generated by an application behind NGINX — a JWT-based API rejecting an expired or malformed token, for instance — pass through NGINX unmodified unless proxy_intercept_errors is engaged, which means the diagnostic path here usually runs through application logs rather than the NGINX error log. NGINX itself only generates 401 directly when auth_basic or a similar access-control module is configured at the NGINX layer.
403 Forbidden from a missing index file to a misread permission bit
A 403 response means NGINX found something matching the request but declined to serve it — the single most consistently misdiagnosed error in this entire list, because the reasons behind a 403 branch across at least five distinct and unrelated causes, and the response itself gives no indication which one applies. A 403 does not reveal whether NGINX, the filesystem, SELinux, an upstream proxy, or the application itself refused the request — that determination requires reading the specific log line, not guessing from the status code alone.
The most frequent cause on a fresh server setup is a directory request with no matching index file and directory listing disabled. When a client requests a path that resolves to a directory rather than a specific file, NGINX looks for a file named in its index directive — typically index.html or index.php — and if none exists, and autoindex is off (the default), it returns 403 rather than silently listing the directory’s contents. The distinguishing log line is explicit:
directory index of "/var/www/html/" is forbidden
Two fixes apply depending on intent. If the directory is meant to have a landing page, the actual fix is placing a valid index file there — an empty or forgotten deployment step, not a configuration bug. If directory browsing is genuinely the desired behavior — a package mirror, a controlled downloads folder — the fix is enabling it explicitly and narrowly:
location /downloads/ {
    root /var/www/example.com/html;
    autoindex on;
    autoindex_exact_size off;
    autoindex_localtime on;
}
Enabling autoindex globally to work around a missing homepage is a mistake that trades a cosmetic error for an actual information-disclosure risk — it exposes every filename and subdirectory in the location to anyone who requests the parent path, which is rarely what anyone actually intends.
The second most frequent cause is a genuine filesystem permission problem, distinguishable in the log by a completely different string:
directory index of "/var/www/html/" is forbidden
versus, for a permissions failure on a specific file:
"/var/www/html/report.pdf" failed (13: Permission denied)
The number in parentheses is the underlying operating-system errno, and it is worth memorizing: (2: No such file or directory) is a 404-track error, while (13: Permission denied) is a 403-track error. Checking the error log for these two specific phrases is the fastest way to know which of the two very differently-fixed problems you’re actually looking at, before touching any configuration file.
Fixing a genuine permission problem means confirming the NGINX worker process’s user — www-data on Debian and Ubuntu, nginx on RHEL-family distributions — has execute permission on every directory in the path leading to the file, plus read permission on the file itself:
chmod 755 /path/to/directories
chmod 644 /path/to/files
Every parent directory in the full path needs the execute bit for the NGINX worker user, not just the final directory holding the file — a single intermediate directory owned by a different user with restrictive permissions breaks the entire chain even when the target file itself looks correctly permissioned in isolation.
Autoindex, symlinks and the SELinux layer that hides behind a 403
Beyond missing index files and straightforward filesystem permissions, three less obvious causes account for most of the remaining 403 responses that survive a first pass of troubleshooting.
Symbolic links are the first. NGINX follows symlinks by default, but the disable_symlinks directive, when set to anything other than off, restricts that behavior — and a restrictive disable_symlinks setting, combined with a symlink target that has different ownership than the link itself, or with SELinux policy blocking the target path, produces a 403 that looks identical to a plain permissions failure in the browser but requires a different fix entirely:
server {
    root /var/www/html;
    disable_symlinks off;
    location / {
        try_files $uri $uri/ =404;
    }
}
The safer middle ground, rather than disabling the check entirely, uses disable_symlinks if_not_owner, which permits symlinks whose target shares the same owner as the link but blocks the ones that don’t — closing off a specific privilege-escalation vector while still allowing the common legitimate case.
SELinux is the second, and the one that produces the most confusing symptom of all: a 403 where the file permissions checked with ls -l look entirely correct. On RHEL-family distributions — Rocky Linux, AlmaLinux, CentOS — SELinux enforces a mandatory access control layer independent of standard Unix permissions, and it can block NGINX from reading files or connecting to sockets even when the standard permission bits say access should be allowed. The tell is checking for SELinux denials directly rather than trusting ls -l:
sudo ausearch -m avc -ts recent
If a denial shows up correlating with the failed request, the fix — after confirming the change actually resolves the error — is to apply the correct SELinux context permanently rather than disabling SELinux entirely, which is a security regression that should never be the production answer:
sudo semanage fcontext -a -t httpd_sys_content_t "/var/www/html(/.*)?"
sudo restorecon -Rv /var/www/html
Disabling SELinux to make an error go away is one of the most common overcorrections in NGINX troubleshooting, and it should be treated as a diagnostic step only, reverted the moment the specific denial is identified and properly permitted.
The third, less common but worth naming, is a web application firewall — ModSecurity is the most widely deployed NGINX-compatible option — inspecting request content and returning 403 for anything matching a rule pattern, entirely independent of filesystem state. A WAF-generated 403 shows up in a separate audit log rather than the standard NGINX error log, and distinguishing it from a filesystem-level 403 requires checking that log specifically; treating a WAF rejection as a permissions bug wastes time chasing chmod changes that were never going to fix a rule match.
404 Not found as a routing problem, not a missing-file problem
A 404 means NGINX could not match the request to an existing file, a defined route, or a configured fallback — and the instinctive assumption that the file is simply missing is wrong often enough to be worth correcting explicitly. The far more common cause in a properly deployed production application is that NGINX is looking in the wrong place, following the wrong rewrite path, or stripping a path segment a backend still expects.
The request-handling sequence that produces a 404 runs through several distinct decision points, and identifying which one failed determines the fix. A rewrite directive can turn a URL into a path that no longer corresponds to anything on disk. A root or alias directive can point at the wrong base directory, causing NGINX to search a filesystem path adjacent to the correct one. A try_files chain can run out of fallback options and hit its final =404 argument because none of the earlier patterns matched. A proxied request can have its path rewritten by proxy_pass‘s trailing-slash behavior in a way that no longer matches anything the backend expects. And, in the case of a genuinely proxied backend, the 404 may not originate at NGINX at all — the upstream application itself may be returning it for a route that doesn’t exist there.
The single fastest triage step is checking whether the same request succeeds when sent directly to the backend, bypassing NGINX entirely. If a direct request to the application server on its internal port returns 200 but the same request through NGINX returns 404, the fault is in NGINX’s path handling — root, alias, rewrite, or the proxy_pass path segment. If the direct request also returns 404, the problem is in the application’s own routing and no NGINX configuration change will fix it.
For static content, the log line distinguishes a genuine missing file from a routing mismatch cleanly:
open() "/var/www/html/assets/logo.png" failed (2: No such file or directory)
That specific path — the one NGINX actually tried to open — is the single most useful piece of information in the whole log entry, because it often immediately reveals a root or alias misconfiguration: if the logged path doesn’t match where the file genuinely lives on disk, the fix is in the location block’s base-directory directive, not in the file system.
Root versus alias, the trailing slash and why try_files exists
The root and alias directives both map a request URI onto a filesystem path, but they build that path differently, and the difference is responsible for more baffling 404s than almost any other single NGINX concept.
root appends the full request URI to the configured directory. With root /var/www/example.com; and a request for /images/photo.jpg, NGINX looks for /var/www/example.com/images/photo.jpg — the location prefix stays part of the path. alias replaces the matched location prefix with the configured directory instead of appending to it. With location /images/ { alias /var/www/media/; }, a request for /images/photo.jpg resolves to /var/www/media/photo.jpg — the /images/ segment from the URL disappears entirely from the filesystem path.
A common mistake is using root where alias was intended, most often when serving a directory whose name on disk doesn’t match its public URL prefix:
# Wrong: this looks for /srv/example-assets/assets/app.css
location /assets/ {
    root /srv/example-assets;
}

# Right: this looks for /srv/example-assets/app.css
location /assets/ {
    alias /srv/example-assets/;
}
The trailing slash on alias is not cosmetic — get it wrong and the concatenated path has no separator between the alias target and the remaining URI, producing a path that never existed on any filesystem. This single missing character is one of the most common sources of an inexplicable 404 on an otherwise correctly reasoned configuration, and it is worth checking as a first step whenever an alias block produces 404s that a matching root block wouldn’t.
try_files exists to define an explicit fallback chain rather than letting a single failed lookup immediately return 404:
location / {
    try_files $uri $uri/ /index.html;
}
This tells NGINX to attempt the exact URI as a file, then as a directory, then fall back to serving /index.html if neither exists — the pattern every single-page application built with React, Vue, or Angular requires, because those frameworks handle their own client-side routing and have no server-side file corresponding to most of their URLs. Without a try_files fallback, a request for /dashboard in a single-page application returns a hard 404, because no file named dashboard exists on the server and NGINX has no instruction to serve the application’s entry point instead.
try_files chains interact badly with rewrite directives placed above them in ways that are easy to miss during a config review: if a rewrite transforms the URI before try_files runs, and the rewritten path is what actually exists on disk, try_files evaluating the original unrewritten URI never finds a match and falls straight through to its final =404 argument even though the target file genuinely exists — a subtle enough interaction that it is one of the most frequently reported “this should work but doesn’t” NGINX bugs on public forums, and the fix is almost always reordering the directives or replacing the interaction with a location block that doesn’t rely on rewrite at all.
Single-page applications, WordPress permalinks and the 404 that isn’t NGINX’s fault
Two specific application patterns account for a disproportionate share of real-world 404 tickets, and both deserve a dedicated, memorized fix rather than a fresh diagnostic pass every time.
Single-page applications — anything built with a client-side router in React, Vue, or Angular — need every non-asset URL to resolve to the same entry point, typically index.html, so the JavaScript router can take over and render the correct view based on the URL itself. The correct location block:
location / {
    try_files $uri $uri/ /index.html;
}
A 404 on a route like /settings/profile in this setup, despite the application working correctly when loaded from its root URL, is the signature of a missing or incorrect try_files fallback — the framework’s client-side router was never given a chance to run, because NGINX rejected the request before the JavaScript ever loaded.
WordPress with “pretty” permalinks produces a functionally identical symptom for a different underlying reason. A URL like /blog/my-post/ corresponds to no actual file or directory on the server; WordPress’s own .htaccess-equivalent routing logic, implemented through NGINX’s try_files, needs to hand unmatched requests to index.php so WordPress’s internal router can resolve them against the database:
location / {
    try_files $uri $uri/ /index.php?$args;
}
The most common single symptom here is that the WordPress admin dashboard loads fine while every front-end permalink returns 404 — because the dashboard is served from /wp-admin/, a real directory with a real index.php, while the pretty permalinks depend entirely on the fallback rule that hands unmatched paths to WordPress’s router. The fix on the WordPress side, once the NGINX try_files directive is confirmed correct, is often just visiting Settings → Permalinks in the WordPress admin and clicking Save without changing anything — an action that flushes WordPress’s own internal rewrite rule cache and frequently resolves the issue when the NGINX side was never actually broken.
For a proxied backend rather than a static-file or PHP application, the equivalent trap is a proxy_pass trailing slash silently rewriting the forwarded path:
# Strips the /api/ prefix before forwarding — backend sees /users
location /api/ {
    proxy_pass http://backend/;
}

# Preserves the full path — backend sees /api/users
location /api/ {
    proxy_pass http://backend;
}
A trailing slash on the URL inside proxy_pass causes NGINX to replace the matched location prefix, exactly like alias does for static files; omitting it causes NGINX to append the full original URI instead. If the backend expects /api/users and NGINX is stripping the /api/ prefix before forwarding, every request the backend receives is missing a segment it needs to route correctly, and the backend’s own 404 gets faithfully relayed back through NGINX — making the fault look like it belongs to the application when the actual cause sits entirely in the proxy configuration.
405 Method not allowed and 406 Not acceptable, the errors nobody debugs
Two codes round out the smaller-traffic end of the 4xx family, both genuinely rare in normal browsing but common enough in API and automated-client contexts to deserve a fast, confident diagnosis rather than confusion when they finally show up.
405 Method Not Allowed means the resource exists but does not support the HTTP method the client used — a GET request to an endpoint that only accepts POST, most commonly. NGINX itself rarely generates this directly for standard proxied traffic; it typically originates in the backend application’s own routing framework, which has explicitly registered which methods a given route accepts and rejects the rest. The exception is NGINX’s own static-file serving, which by default only handles GET, HEAD, and a small set of other safe methods for files served directly from disk — a PUT or DELETE request aimed at a static asset location, rather than a proxied API endpoint, returns 405 straight from NGINX with no application ever involved.
The fix, when the 405 is genuinely unexpected — a route that should accept POST but is rejecting it — almost always lives in the application’s routing configuration rather than in NGINX, since NGINX’s role for a proxied request is simply to forward the method through unmodified; confirming this means checking whether the method reaches the backend correctly by inspecting $request_method in the access log against what the client actually sent, ruling out an NGINX-side transformation before assuming the application logic itself has a bug.
406 Not Acceptable is rarer still, and appears when content negotiation — a client’s Accept header specifying a format the server cannot produce — fails entirely. It shows up almost exclusively in API contexts where a client explicitly requests a response format, such as Accept: application/xml, that the backend has not implemented, and the fix is either implementing the requested format or adjusting the client to accept what the server actually produces; NGINX itself has essentially no role in generating this code for typical deployments, since content negotiation logic almost always lives in the application layer.
Neither code justifies extensive NGINX-level troubleshooting on its own. Both are useful primarily as confirmation that a request reached the application layer successfully and was rejected there on its own logic, which is itself a useful piece of information when triaging a broader incident — it rules out NGINX routing and connectivity as the cause, pointing the investigation squarely at the application’s request-handling code instead.
413 Content too large and the client_max_body_size ceiling
A 413 response — renamed from “Payload Too Large” to “Content Too Large” in RFC 9110’s refinement of the status code’s official phrasing, though “Request Entity Too Large” remains the far more commonly seen wording in practice — means the client’s request body exceeded a size limit NGINX enforces before the request body is even fully read. This is one of the cleanest single-cause errors in the entire list: it happens because client_max_body_size is set lower than the actual upload the client is attempting, and the fix is exactly as direct as the diagnosis.
NGINX checks the Content-Length header against the configured limit and rejects the request immediately if it exceeds that value, without processing the request body at all — meaning the rejection happens before any bandwidth is wasted transferring the oversized payload, a deliberate efficiency choice. The default value of client_max_body_size is one megabyte, a limit set decades ago for a web that mostly exchanged small HTML documents and form submissions, and one that modern applications — file uploads, API payloads carrying embedded images, bulk data imports — regularly exceed without anyone having deliberately configured anything unusual.
The fix is a single directive, settable at the http, server, or location context, with more specific contexts overriding broader ones:
http {
    client_max_body_size 32m;
}
Or scoped narrowly to just the upload endpoint that needs it, leaving the rest of the site at a tighter default for defense against abuse:
location /upload/ {
    client_max_body_size 100m;
}
The log line confirming this diagnosis states the exact size NGINX rejected, which is worth checking even when the fix seems obvious, because it sometimes reveals a client sending far more data than expected — a sign of a bug on the client side rather than a legitimately larger file that just needs a higher limit:
client intended to send too large body: 104857600 bytes
Raising the limit is not free of security implications, and the note attached to NGINX’s own documentation for this directive is explicit about it: increasing client_max_body_size for larger uploads increases exposure to denial-of-service attacks built around consuming server resources with oversized request bodies. The correct posture is setting the limit to the smallest value that legitimately accommodates real usage, scoped as narrowly as possible to the specific locations that need it, rather than raising it globally to a large value out of convenience.
A 413 can also originate from a layer other than NGINX entirely — a backend application server with its own independent body-size limit, for instance Node.js’s default Express body-parser limit, or PHP’s own post_max_size and upload_max_filesize settings in php.ini. Raising client_max_body_size alone does not fix a 413 if the backend’s own limit is lower than NGINX’s — both layers need to agree, and troubleshooting a persistent 413 after confirming the NGINX-level fix means checking every layer in the request path, not assuming the fix that worked at the edge has propagated to everything behind it.
414 URI too long and the header buffer errors that travel together
A 414 response means the request line itself — the URL, not the headers or the body — exceeded the buffer NGINX allocates for it. This is the least common of the buffer-related errors in ordinary traffic, because legitimate URLs rarely approach the default limits, but it shows up reliably in two specific patterns: poorly designed APIs that encode large amounts of state directly into query-string parameters, and automated scanning tools probing for vulnerabilities by appending long strings of test payloads to the URL path.
The governing directive is the same large_client_header_buffers that controls the 400-triggering header-field limit discussed earlier, but the distinction between the two failure modes is precise and worth stating plainly: if the request URI line itself is larger than the configured buffer, NGINX returns 414; if a different header line — most often Cookie — exceeds the buffer, NGINX returns 400 instead. Same directive, same underlying buffer mechanism, two different status codes depending on which specific part of the request overflowed it.
large_client_header_buffers 4 16k;
The fix is identical in mechanism to the 400 fix — raise the per-buffer size, not the buffer count — but the underlying cause usually calls for a different remediation than a cookie-bloat problem does. A legitimately oversized query string is almost always a sign that state belongs in the request body or in server-side session storage rather than encoded into the URL. A GET request carrying pages of serialized filter parameters, sort orders, and pagination state in its query string is both hitting a hard technical limit and creating a URL that is difficult to bookmark, share, or cache correctly — the buffer increase resolves the immediate error, but redesigning the endpoint to accept a POST with the filter state in the body, or to reference a saved filter by an opaque ID, resolves the actual design problem that produced the oversized URL in the first place.
When a 414 shows up as a spike rather than a steady baseline, correlate it against source IP addresses in the access log before assuming it’s a legitimate traffic pattern that needs accommodating — a burst of 414s from a small number of IPs sending deliberately malformed, oversized request lines is a common signature of automated vulnerability scanning, and the correct response is blocking or rate-limiting the source, not raising buffer limits to accept the payloads the scanner is testing.
429 Too many requests, limit_req and the difference between a limit and an attack
A 429 response means the server is deliberately refusing a request because the client has exceeded a configured rate limit — the one status code in this entire list that represents an intentional, working control doing exactly what it was configured to do, rather than a failure of any kind. Seeing 429s in a log is, correctly interpreted, evidence that rate limiting is functioning, not evidence that something is broken — though a sudden unexpected spike in legitimate users hitting the limit does indicate the configured threshold may need adjusting.
NGINX implements request-rate limiting through the limit_req module, configured in two parts: a shared-memory zone defined once at the http level, and the actual limit applied within a server or location block:
http {
    limit_req_zone $binary_remote_addr zone=api_limit:10m rate=10r/s;
}

server {
    location /api/ {
        limit_req zone=api_limit burst=20 nodelay;
        proxy_pass http://backend;
    }
}
$binary_remote_addr keys the rate limit by client IP address, the shared memory zone tracks request counts against that key, rate=10r/s sets the sustained limit, and burst=20 nodelay allows a controlled excess above the sustained rate to pass through immediately rather than being queued and delayed, rejecting only what exceeds the burst allowance entirely.
By default, NGINX returns 503 for rate-limited requests, not 429 — a default that predates 429’s standardization in RFC 6585 and that most modern deployments deliberately override, because a 503 signals a temporary server-capacity problem to clients and monitoring systems, while 429 correctly signals a client-specific rate limit that will resolve if the client simply slows down. The override is one directive:
limit_req_status 429;
limit_conn_status 429;
Getting this distinction right matters operationally, not just semantically, because automated clients and API consumers are often programmed to react differently to the two codes — treating a 503 as a signal to fail over to a different endpoint or alert on-call staff, while treating a 429 as a signal to simply back off and retry after a delay, ideally guided by a Retry-After header the server includes in the response.
A parallel directive, limit_conn, controls simultaneous connection count rather than request rate, useful for capping how many concurrent connections a single client can hold open regardless of how frequently they’re making new requests:
http {
    limit_conn_zone $binary_remote_addr zone=conn_limit:10m;
}

server {
    limit_conn conn_limit 10;
}
Distinguishing a legitimate rate-limit trigger from an actual attack requires looking past the status code to the pattern behind it. A single IP hitting the same endpoint at a sustained rate slightly above the configured threshold, during a period that correlates with a legitimate marketing campaign or a mobile app’s normal polling behavior, calls for raising the limit or exempting the endpoint from strict limiting. A rate limit rejecting thousands of requests per minute from a wide, rapidly rotating set of IP addresses hitting varied endpoints is a different situation entirely, and the correct response escalates beyond limit_req tuning into IP-reputation blocking or a dedicated bot-mitigation layer — fail2ban‘s built-in nginx-limit-req filter, which parses the NGINX error log for rate-limiting rejection messages and automatically bans repeat offenders at the firewall level, is a common middle-ground tool for exactly this escalation, configured to trigger only after a genuinely abusive pattern rather than a single burst.
Health-check and monitoring endpoints should be explicitly exempted from rate limiting, since an automated monitoring system polling a health-check URL at a fixed interval will otherwise eventually trip the same limit configured for genuine user traffic, producing false-positive downtime alerts that have nothing to do with the service’s actual health:
location /health {
    limit_req off;
    return 200 'OK';
}
431 Request header fields too large in the HTTP/2 and load-balancer era
A 431 response, standardized separately from the buffer-based 400 and 414 errors NGINX generates natively, means the complete set of request header fields together exceeds a limit — distinct from the single-header-line limit that produces a 400, and distinct from the single-request-line limit that produces a 414. This code has become substantially more common with the rise of HTTP/2 and modern authentication schemes that embed large tokens directly in headers, particularly JSON Web Tokens carried in an Authorization header on every single request rather than referenced by a smaller session identifier.
The most frequent modern trigger is exactly this pattern: an Authorization: Bearer header carrying a JWT that has grown large because it encodes an extensive set of claims — roles, permissions, group memberships — directly in the token payload rather than requiring a lookup against a smaller opaque reference. A JWT that started small during initial development and grew as more claims were added over an application’s lifetime is a common, gradual path toward hitting a header-size limit that nobody deliberately configured against.
In Kubernetes environments specifically, this shows up as a well-documented and frequently reported pattern behind NGINX Ingress controllers, where the underlying NGINX buffer configuration is exposed through the ingress controller’s own ConfigMap rather than a directly editable nginx.conf — a layer of indirection that trips up a large number of people searching for the standard fix, since editing the ConfigMap key that appears in most search results sometimes does not actually resolve the issue if the ingress controller’s default annotations or a separate proxy layer in front of it retains its own independent limit.
The direct NGINX-level fix follows the same large_client_header_buffers mechanism already covered for 400 and 414, since these three codes are functional siblings differentiated only by which specific part of the header block overflowed:
large_client_header_buffers 8 32k;
When a proxy chain includes more than one layer — a CDN or load balancer in front of NGINX, or NGINX itself proxying to a second internal NGINX instance — every layer needs its buffer limits raised in concert. A fix applied only at the outermost layer does nothing if an inner layer, invisible from the outside and easy to forget during a config review, still enforces the older, smaller default; the resulting symptom is a 431 that appears to resist every documented fix, when the actual cause is simply that one hop in a multi-hop chain was never touched.
As with the oversized-cookie 400 case, the durable long-term fix is architectural rather than configuration-based: reducing what actually needs to travel in request headers on every single call — shrinking JWT claim sets down to the minimum needed for routing and authorization decisions, moving detailed permission data to a server-side lookup keyed by a small token, or splitting an overloaded authentication header into a smaller reference plus a server-side cache — resolves the problem at its source rather than simply raising the ceiling it keeps approaching as the application continues to grow.
495, 496 and 497, the SSL-specific codes almost nobody recognizes
Three nonstandard status codes belong to NGINX’s SSL module specifically, and their obscurity is inversely proportional to how often they actually appear in production logs on any site handling client-certificate authentication or mixed HTTP-and-HTTPS traffic on the same port.
497 — “HTTP Request Sent to HTTPS Port” — is the most common of the three and the easiest to fix. It fires when a client sends a plain, unencrypted HTTP request to a port NGINX has configured exclusively for TLS, most often port 443. The scenario that produces this in practice almost always involves a hard-coded http:// URL somewhere in an application’s own codebase, configuration file, environment variable, or database record that should have been https:// — the client dutifully follows the link exactly as instructed and lands on a TLS-only port speaking the wrong protocol. The direct fix uses NGINX’s own error_page 497 directive to catch the mismatched request and redirect it to the correct protocol automatically, rather than showing the raw error:
server {
    listen 443 ssl;
    server_name example.com;
    ssl_certificate /etc/nginx/ssl/cert.pem;
    ssl_certificate_key /etc/nginx/ssl/key.pem;
    error_page 497 =301 https://$host:$server_port$request_uri;
}
This catches the malformed protocol internally and issues a 301 redirect back to the client with the correct scheme, preserving the original port and full request URI. A separate server block listening on plain port 80 handles the ordinary case of a user manually typing http:// into a browser address bar:
server {
    listen 80;
    server_name example.com;
    return 301 https://$host$request_uri;
}
Fixing the surface symptom with the redirect does not remove the underlying source of the problem — every hard-coded http:// reference still exists somewhere in the codebase and will keep triggering the same corrective redirect indefinitely. Auditing configuration files, environment variables, and stored database records for hard-coded protocol strings and correcting them at the source is the durable fix; the error_page 497 redirect is a safety net, not a replacement for that audit.
495 — “SSL Certificate Error” — and 496 — “SSL Certificate Required” — both arise specifically in mutual TLS (mTLS) configurations where NGINX is set to verify client certificates, controlled by the ssl_verify_client directive. The distinction between the two is precise: 496 means the client presented no certificate at all when one was required; 495 means the client presented a certificate, but it failed verification — an expired certificate, one signed by a certificate authority not in NGINX’s trusted list, or a chain missing an intermediate certificate needed to link it back to a trusted root.
The relevant configuration:
ssl_client_certificate /etc/nginx/trusted_ca.pem;
ssl_verify_client on;
ssl_verify_depth 3;
ssl_verify_client on rejects any request lacking a valid client certificate outright, which is the strict posture appropriate for an internal service-to-service API or an admin interface where every caller is expected to authenticate with a certificate. ssl_verify_client optional instead accepts requests both with and without a certificate, verifying one when present but not rejecting its absence — a posture suited to an endpoint serving both authenticated and anonymous traffic, where the application itself makes the final access decision based on the $ssl_client_verify variable rather than NGINX enforcing it unconditionally:
if ($ssl_client_verify != SUCCESS) {
    return 403;
}
ssl_verify_depth, defaulting to 1, is a frequently overlooked cause of a 495 that otherwise looks inexplicable — a value of 1 only allows a single intermediate certificate between the client’s certificate and a trusted root; any certificate chain with more than one intermediate fails verification until this value is raised to match the actual chain depth in use. The handshake itself completes successfully before any of this verification logic runs, which is exactly why a certificate problem here surfaces as an HTTP-layer status code rather than a lower-level TLS connection failure — the client sees what looks like an ordinary 400-family response rather than a connection that failed to establish at all, which is often the detail that misleads people into debugging the wrong layer first.
Custom error pages for both make the failure mode clear to legitimate clients rather than leaving them staring at a bare four-hundred-something with no context:
error_page 496 =400 /errors/cert-missing.html;
error_page 495 =400 /errors/cert-invalid.html;
500 Internal server error and the difference between NGINX’s fault and the backend’s
A 500 response is the internet’s oldest and vaguest error — the HTTP equivalent of “something went wrong, and no further detail is being offered.” The single most important fact to internalize about a 500 appearing behind NGINX: the response almost never originates in NGINX itself. It is overwhelmingly a signal relayed from an upstream application — PHP-FPM, Node.js, Python, Ruby, Go — that crashed, threw an unhandled exception, or returned malformed output that NGINX is simply passing through unmodified. NGINX generates its own 500 only in a narrow set of circumstances: an internal memory allocation failure, a severe misconfiguration that prevents request processing entirely, or a small number of edge cases in specific modules.
Telling an NGINX-generated 500 apart from an upstream-relayed one is the single fastest triage decision available, and it is made by checking two different logs rather than one. If the failure occurred during the execution of a proxied or FastCGI-forwarded request and fastcgi_intercept_errors or proxy_intercept_errors is enabled, the actual root cause lives in the backend’s own error log — PHP-FPM’s log for a PHP application, the application server’s stdout or a dedicated log file for anything else — not in NGINX’s. If the error log shows an internal NGINX-generated message about memory allocation or client-connection handling with no corresponding upstream activity, the fault genuinely sits in NGINX’s own operating environment: usually resource exhaustion on the host itself, rather than anything a configuration change to a location block will fix.
A frequently missed detail explains why a 500 sometimes shows a bare, unhelpful footer reading something like nginx/1.24.0 (Ubuntu): that footer indicates NGINX served its own default error page, confirming NGINX was the layer that generated the response the client actually saw — but it says nothing about whether the underlying cause was NGINX’s own fault or a backend failure NGINX chose to intercept and replace with its generic page. Setting server_tokens off; in the http block removes the version and operating-system detail from this footer and from the Server response header globally, which is a sound security practice regardless of its relevance to any specific error — it denies an attacker easy version-fingerprinting information — though the word “nginx” itself remains, since that string is hard-coded into the default error page template rather than pulled from server_tokens.
For a PHP application specifically, the practical debugging sequence starts with the PHP-FPM error log rather than NGINX’s:
tail -f /var/log/php-fpm/error.log
An empty PHP-FPM log does not mean there was no error — PHP’s own error reporting may be configured to write elsewhere, or worker output may not be captured by the configured logging destination at all, which is a common trap that leads people to conclude incorrectly that the problem must be in NGINX simply because the log they expected to hold the answer is silent.
A syntax error, an undefined variable treated as fatal under strict error reporting, a database connection failure, or a memory-limit exhaustion in the PHP script are all common concrete causes that surface as a bare 500 at the browser while the actual descriptive error sits waiting in the PHP error log — checking memory_limit in the active php.ini used specifically by the FPM pool serving web requests, rather than the CLI’s separate php.ini, is a frequent point of confusion, since PHP’s command-line interface and its FPM daemon can load entirely different configuration files even on the same server.
PHP-FPM, fastcgi_intercept_errors and the silent-swallow problem
The interaction between NGINX and PHP-FPM around error handling deserves its own dedicated treatment, because a single directive — fastcgi_intercept_errors — silently changes which layer’s error output actually reaches the end user, and getting this setting wrong in either direction produces a genuinely confusing debugging experience.
When fastcgi_intercept_errors on; is set, NGINX treats any 4xx or 5xx status code coming back from PHP-FPM as its own error condition and substitutes whatever custom error_page NGINX has configured for that status, discarding PHP’s own error output entirely — including any detailed stack trace or error message PHP itself generated, which the developer may have specifically enabled for debugging purposes. This is frequently the actual reason a developer sees a generic NGINX error page while insisting they configured PHP to display detailed errors: the PHP-level configuration is working correctly and generating the detailed output exactly as intended, but NGINX is silently discarding it before it ever reaches the browser.
location ~ \.php$ {
    fastcgi_intercept_errors on;
    error_page 500 /custom-500.html;
    fastcgi_pass unix:/run/php/php8.2-fpm.sock;
}
Temporarily disabling this setting during active debugging — fastcgi_intercept_errors off;, or simply commenting the line out — restores PHP’s own detailed error output to the browser, which is invaluable while chasing down a specific bug but must be reverted before returning to production, since exposing PHP stack traces, file paths, and potentially database credentials embedded in error messages to public users is a real and specific information-disclosure risk that has led to real security incidents.
Beyond the intercept-errors interaction, a distinct and common category of PHP-FPM-specific 500s and 502s arises from a mismatch between how NGINX and PHP-FPM agree to communicate. PHP-FPM listens on either a Unix socket or a TCP address, configured in its own pool configuration file, and NGINX’s fastcgi_pass directive must point at exactly the same address:
# PHP-FPM pool configuration
listen = /run/php/php8.2-fpm.sock
listen.owner = www-data
listen.group = www-data
listen.mode = 0660

# NGINX configuration — must match exactly
fastcgi_pass unix:/run/php/php8.2-fpm.sock;
A mismatch here — a stale socket path left over from a PHP version upgrade, a pool configuration that changed without the corresponding NGINX configuration being updated to match — produces a connection failure that surfaces as a 502, not a 500, because NGINX cannot reach PHP-FPM at all rather than reaching it and receiving an error response; distinguishing between the two failure modes by log signature (covered in the following section on 502) is often the fastest way to know whether the actual fault is a socket mismatch or a genuine application-level PHP error.
A worker-timeout scenario deserves specific mention because it produces a 500 through an unusual and easily misdiagnosed mechanism. PHP-FPM’s own request_terminate_timeout setting kills a worker process that has been running for longer than the configured limit, independent of any timeout NGINX itself enforces — meaning a request can produce a 500 from a killed PHP-FPM worker even when every NGINX-side timeout directive is generously set. The correct fix is finding and fixing the specific slow code path responsible, or, if a specific known-slow endpoint genuinely needs more time, raising request_terminate_timeout for that endpoint specifically rather than globally across the entire pool — a global increase means a single genuinely broken infinite loop in unrelated code can now hold a worker process for much longer before being forcibly terminated, tying up pool capacity that other, healthy requests need.
502 Bad gateway, the single most common production NGINX failure
A 502 response means NGINX, acting as a proxy, received an invalid response — or no response at all — from the upstream server it forwarded the request to. This is, by a wide margin, the single most frequently encountered NGINX error in real production environments, precisely because NGINX so commonly sits in front of an application server, and the application server is where most of the moving, breakable parts of any deployment actually live.
The core distinction that separates 502 from every other proxy-related error in this article: a 502 means NGINX never got a usable response from the upstream at all — a connection refused, a malformed response, or a process that died mid-reply — while a 504 means the connection to the upstream succeeded and NGINX is simply still waiting for it to finish. Confusing the two wastes diagnostic effort, because the fixes point in genuinely different directions: a 502 investigation starts with “is the upstream process even running,” while a 504 investigation starts with “why is the upstream taking this long.”
By a substantial margin, the most common single cause in real production incidents is a backend process that has crashed, was never started, or exited unexpectedly — the log signature is unambiguous:
connect() failed (111: Connection refused) while connecting to upstream
“Connection refused” is the operating system’s kernel reporting that nothing is listening on the port or socket NGINX attempted to reach — NGINX did its job correctly; there is simply no application process there to forward the request to. The immediate diagnostic sequence checks whether the backend service is genuinely running:
sudo systemctl status myapp
sudo systemctl start myapp
sudo journalctl -u myapp -n 200
For a containerized backend, the equivalent check confirms the container’s actual state rather than assuming it:
docker ps -a | grep myapp
docker logs myapp --tail 200
A second common cause is a straightforward misconfiguration: proxy_pass or fastcgi_pass pointing at an incorrect IP address, port, or socket path — a value left over from a previous deployment, a typo introduced during a configuration edit, or an environment-specific value that was never updated when moving between staging and production. Double-checking these directives against the actual, currently-running backend address is a fast, cheap first step that resolves a meaningful share of 502 incidents before any deeper investigation is needed.
A third, less obvious cause involves DNS resolution behavior specific to how NGINX handles upstream hostnames: NGINX resolves a hostname used in proxy_pass at startup by default and caches that resolved address, rather than re-resolving it on every request. If the upstream hostname’s IP address changes after NGINX started — common in cloud environments where backend instances are dynamically provisioned and torn down, or DNS-based service discovery reassigns addresses — NGINX continues sending requests to the stale, cached address until it is restarted or reloaded, producing 502s that appear intermittently and correlate suspiciously with backend infrastructure changes rather than any application code deployment. Using NGINX’s resolver directive with a short, explicit TTL and a variable-based proxy_pass target forces re-resolution rather than relying on the default startup-time caching behavior.
A fourth, increasingly common cause in microservice architectures involving HTTPS between NGINX and its upstream: a certificate mismatch or an expired certificate on the upstream side causes the TLS handshake between NGINX and the backend to fail, which NGINX reports to the client as a 502 rather than any TLS-specific error, since the failure happened on the internal hop rather than the client-facing connection. A particularly sneaky variant involves a broken certificate chain on the upstream — missing an intermediate certificate — where desktop browsers may still succeed because they cache intermediate certificates from previous unrelated connections, while a proxy or API client with no such cache rejects the connection outright, producing a 502 that appears to work fine when tested manually in a browser but fails consistently for automated clients and for NGINX itself acting as the proxying client.
Diagnosing 502 systematically, from socket paths to SELinux denials
Given how many distinct root causes converge on the identical 502 status code, a fixed diagnostic sequence saves far more time than guessing based on whichever cause was responsible for the last incident.
Step one is always the error log, because NGINX writes the actual cause of essentially every 502 there in reasonably plain language, and skipping straight to configuration changes without reading it first is the single most common way to waste time on an incident that the log would have resolved in seconds:
tail -f /var/log/nginx/error.log
If the log file is empty or does not exist at the expected path, NGINX may be writing to journald instead of a flat file — a common default in newer systemd-managed distributions — and the equivalent check becomes:
sudo journalctl -u nginx -n 100
Step two matches the specific log line against the seven causes that account for nearly every 502 seen in production, roughly in order of how frequently each actually shows up. A connect() failed (111: Connection refused) line means the backend process is down — check whether it’s running and start it if not. A connect() failed (110: Connection timed out) line during the connecting phase, distinct from a reading phase timeout, suggests network-level unreachability rather than a slow backend — check firewall rules and network routing between the NGINX host and the backend. A socket-path error — connect() failed (2: No such file or directory) when the target is a Unix socket — means the socket file the configuration points at simply doesn’t exist, almost always because PHP-FPM or an equivalent process crashed and took its socket file down with it, or because a configuration change moved the socket path without a corresponding NGINX update. A “socket file exists but NGINX cannot access it” scenario, distinguishable by a permission-denied variant of the same connect error, points at either a straightforward ownership mismatch between the socket file and the NGINX worker user, or, on RHEL-family systems, an SELinux denial — checked the same way as the earlier 403 SELinux case, with ausearch -m avc -ts recent.
On RHEL-based distributions specifically, SELinux blocking NGINX from connecting to a PHP-FPM socket or a network port is a commonly overlooked cause precisely because the symptom looks identical to a genuine permissions problem, and the error log offers no direct hint that SELinux is the actual layer responsible. Checking for a relevant denial before assuming the fix is a straightforward chown or chmod change avoids the frustrating experience of “correcting” permissions that were never actually wrong, watching the 502 persist, and eventually discovering SELinux was silently blocking the connection the entire time regardless of the standard Unix permission bits.
A header-size mismatch between NGINX and a proxied application is a less common but genuinely distinct cause worth naming separately: when a backend sets an unusually large number of cookies or custom response headers, the combined response header size can exceed NGINX’s default proxy buffer allocation, triggering a 502 with a specific, identifiable log message about the upstream sending headers too large for the configured buffer — a symptom that looks unrelated to a request-side header problem but is fixed with a parallel directive on the response side rather than the request side:
proxy_buffer_size 16k;
proxy_buffers 4 16k;
Once the specific cause is confirmed through the log, the fix is almost always narrow and targeted — restart a crashed service, correct a misconfigured address, fix a socket permission, or raise a buffer size — rather than a broad, speculative change to timeout values or worker counts that happens to coincide with the problem resolving itself for unrelated reasons, such as the backend recovering on its own during the interval spent making unrelated changes.
503 Service unavailable, capacity limits and the maintenance-page pattern
A 503 response means the server is temporarily unable to handle the request — a status explicitly intended to signal a transient condition rather than a permanent failure, distinguishing it from the open-ended, could-mean-anything nature of a 500. NGINX generates 503 directly in several specific, deliberate circumstances, and distinguishing “NGINX is choosing to say 503” from “something crashed and 503 leaked out by accident” is the key diagnostic question.
The clearest deliberate case is a planned maintenance window, implemented with a dedicated location block or a return 503 directive gated by a marker file’s presence, allowing operators to take a site offline for maintenance cleanly rather than letting requests fail unpredictably against a half-deployed application:
server {
    if (-f /var/www/maintenance.flag) {
        return 503;
    }
    error_page 503 /maintenance.html;
    location = /maintenance.html {
        root /var/www/errors;
        internal;
    }
}
A well-designed maintenance-mode 503 should include a Retry-After header, giving well-behaved clients and search engine crawlers an explicit signal for how long to wait before retrying, rather than leaving them to guess — search engines in particular treat a 503 with a clear Retry-After value as a legitimate signal to avoid dropping the page from their index during a brief planned outage, versus treating an unexplained, sustained pattern of 503s as evidence the site is actually gone.
The second deliberate case is rate limiting configured to reject with the module’s own default status rather than the more semantically correct 429 covered earlier — a legacy default that predates 429’s wider adoption and that many existing configurations simply never updated. The third deliberate case is a load-balanced upstream where every backend server has simultaneously failed its health check, leaving NGINX with no healthy target to route to at all — a genuinely serious situation distinguishable from routine single-backend failures by checking the upstream block’s configured server list against which specific servers the health-check mechanism currently considers down.
An undeliberate 503 — one that appears without any maintenance flag set, any rate limit configured, or any obvious load-balancer failure — points toward genuine resource exhaustion at the NGINX process level itself, most often connection-slot exhaustion covered in more detail in the following sections on worker_connections and file-descriptor limits: when every available connection slot is occupied, often because slow upstream responses are holding connections open far longer than intended, NGINX has no capacity left to accept new incoming connections and returns 503 to signal it, correctly, rather than accepting a request it has no ability to actually process.
A 503 spike that correlates precisely with a deployment, rather than a traffic spike, usually points at insufficient rollout coordination, where new application instances are still starting up and failing health checks at the exact moment old instances are being terminated, leaving a brief window with zero healthy backends — a problem solved at the deployment orchestration level (staggered rollouts, readiness gates that block traffic routing until an instance genuinely passes its health check) rather than at the NGINX configuration level, since NGINX is here correctly reporting a real, if brief and self-resolving, capacity gap rather than failing due to any fault of its own.
504 Gateway timeout and the three-phase timeout model NGINX actually uses
A 504 response means NGINX successfully reached the upstream server — the connection itself succeeded, distinguishing this cleanly from a 502 — but the upstream did not finish responding before NGINX’s configured timeout expired. The default timeout governing this, proxy_read_timeout, is sixty seconds, a value that has remained NGINX’s default for a very long time and that a meaningful share of production incidents simply run straight into the moment an endpoint’s genuine processing time — a large report generation, a bulk data export, a slow third-party API call the backend depends on — happens to exceed it.
The log signature confirming a 504 specifically, as distinct from the connection-level failure that produces a 502, names the exact phase that timed out:
upstream timed out (110: Connection timed out) while reading response header from upstream
“While reading response header” is the critical phrase: it confirms the TCP connection to the upstream succeeded and NGINX was actively waiting for a response that never arrived in time — a fundamentally different failure than the connection-refused signature that characterizes most 502s.
NGINX tracks three genuinely distinct timeout phases for a proxied connection, each governed by its own independent directive, and understanding which phase actually failed is what tells you which specific directive to change rather than blindly raising all of them together:
proxy_connect_timeout 10s;
proxy_send_timeout 60s;
proxy_read_timeout 60s;
proxy_connect_timeout governs how long NGINX waits to establish the initial TCP connection to the upstream — a timeout here almost never indicates a slow application and almost always indicates the upstream is unreachable at the network level or the connection backlog is already full, which behaves more like a 502-track problem than a genuine 504-track one even though it technically produces a timeout. proxy_send_timeout governs the interval between successive writes while NGINX is transmitting the request body to the upstream, relevant mainly for large uploads. proxy_read_timeout — by a wide margin the one that matters in the overwhelming majority of real 504 incidents — governs the interval between successive reads while NGINX waits for the upstream’s response, and it is what actually fires when a backend is doing genuinely slow work: a complex database query, an expensive synchronous computation, or a call out to a third-party API that is itself responding slowly.
Reflexively raising proxy_connect_timeout when the actual log line specifies a read-phase timeout accomplishes nothing — the fix has to target the specific phase the error log names, and applying the wrong directive is one of the most common wasted debugging cycles in this entire subject, precisely because all three directives share the word “timeout” and look interchangeable to someone who hasn’t read the log line carefully.
For a PHP-FPM-fronted application specifically, the equivalent set of directives governs the FastCGI connection rather than a generic proxy connection, and both layers need independent attention since they time out independently of each other:
location ~ \.php$ {
    fastcgi_connect_timeout 60s;
    fastcgi_send_timeout 90s;
    fastcgi_read_timeout 90s;
}
The rule that governs a multi-layer proxy chain — NGINX in front of Varnish in front of a second NGINX in front of PHP-FPM, for instance, a genuinely common production topology — is that each outer layer’s timeout should be set greater than or equal to the layer immediately inside it. Getting this backward produces a confusing symptom where the outer layer times out and returns its own 504 to the client while the inner layer is still legitimately working and would have produced a valid response given a few more seconds — the outer layer simply never gave it the chance.
Simply raising proxy_read_timeout to a large value is frequently the wrong instinct even when it makes the immediate symptom disappear, because a backend that genuinely and routinely needs more than sixty seconds to respond is very often signaling an underlying performance problem that deserves fixing at the source — an unindexed database query, a synchronous call that should be asynchronous, an N+1 query pattern — rather than being accommodated indefinitely by an ever-larger timeout value that just delays when the same underlying problem resurfaces at a worse moment under heavier load.
The phantom worker problem and why raising timeouts is not a fix
A specific and genuinely underappreciated failure mode connects PHP-FPM’s own internal behavior to NGINX’s timeout handling in a way that makes naive timeout-raising actively counterproductive rather than merely ineffective, and it is worth understanding in detail before reaching for a larger fastcgi_read_timeout as a fix.
When NGINX’s fastcgi_read_timeout fires, NGINX closes its side of the connection to PHP-FPM and returns a 504 to the client — but PHP-FPM has no way of knowing this happened. The PHP-FPM worker process that was handling the request continues executing exactly as before, completely unaware that the client-facing connection has already been torn down. It eventually finishes its work, builds the complete response, and attempts to write that response to a socket that nobody is reading from anymore, since NGINX gave up and moved on. This is the phantom worker problem, and it is the central operational trap hiding behind the 504 symptom: the PHP-FPM worker that produced the response the client never received continues consuming a slot in PHP-FPM’s finite worker pool for the entire duration of its actual execution time, not just for the sixty seconds NGINX was willing to wait.
The practical consequence compounds under any kind of load: if a specific slow endpoint is genuinely taking, say, ninety seconds to complete, and NGINX’s fastcgi_read_timeout is set to sixty, every single request to that endpoint ties up a PHP-FPM worker slot for the full ninety seconds of actual execution even though NGINX gave up and reported failure to the client at the sixty-second mark. Under sustained traffic to the slow endpoint, PHP-FPM’s entire worker pool can become saturated with phantom workers that are each still running, each guaranteed to produce a response nobody will ever see, while genuinely new and potentially fast requests queue up behind them with no available worker to serve them at all — turning one slow endpoint into a total outage for the entire application, since PHP-FPM cannot distinguish a phantom worker from a legitimate one and has no mechanism to reclaim the slot early just because NGINX gave up on the client-facing side.
This is precisely why simply raising the timeout is never the complete fix, and can actively make an incident worse rather than better. Raising fastcgi_read_timeout from sixty to ninety seconds does eliminate the specific 504 for that one slow endpoint — but it also means NGINX itself now holds its own worker connection open for the full ninety seconds waiting on a response, consuming an NGINX-side connection slot for half again as long as before, which under sustained concurrent load to the same slow endpoint accelerates NGINX’s own connection-capacity exhaustion rather than PHP-FPM’s, simply relocating the same underlying resource-exhaustion problem to a different, less obviously connected layer.
The durable fix operates on two fronts simultaneously rather than treating either the timeout value or the underlying slowness in isolation. First, PHP-FPM’s own request_terminate_timeout should be set slightly below NGINX’s fastcgi_read_timeout, so that PHP-FPM itself proactively kills a runaway worker before NGINX gives up waiting on it — reclaiming the worker slot promptly rather than letting it run to a natural but pointless completion nobody will ever see. Second, and more fundamentally, the actual slow code path deserves direct investigation and repair — an unindexed database query, a synchronous external API call blocking the entire request, an N+1 query pattern iterating unnecessarily — because a timeout value, however carefully tuned in coordination with request_terminate_timeout, only ever manages the symptom of underlying slowness; it never addresses the cause, and the cause is where sustained capacity actually gets recovered.
Worker_connections, worker_rlimit_nofile and the file descriptor ceiling
A distinct category of failure originates not from any specific request-handling directive but from a hard operating-system ceiling on how many files a process can have open simultaneously — a ceiling that, once hit, produces a cascade of failures across nearly every error code covered in this article at once, because file descriptors are the shared, finite resource underlying every single connection NGINX handles, whether to a client or to an upstream.
Every connection NGINX manages — a client socket, an upstream socket, an open log file, a temporary file created to spill an oversized buffer to disk, an entry held open by open_file_cache — consumes one file descriptor per worker process. In reverse-proxy mode specifically, a single in-flight request typically ties up two sockets simultaneously — one to the client, one to the upstream — meaning file-descriptor demand under proxy workloads runs at roughly double the raw active-connection count, a detail that catches people who calculated their limits based on connection count alone without accounting for the doubling proxy mode introduces.
The failure signature is distinctive and severe once it appears:
accept4() failed (24: Too many open files)
Once this specific error appears, the consequences compound rapidly and can make the situation actively harder to diagnose in real time: NGINX cannot accept new connections, cannot open new upstream sockets to forward existing requests, and in the worst case cannot even write additional lines to its own error log, because writing a log entry itself requires an available file descriptor — meaning the very system meant to explain what’s happening can go silent at precisely the moment its explanation is most needed, with existing already-established connections continuing to serve normally while anything new simply cannot land.
Two separate, independently-configured limits interact here, and the lower of the two always wins regardless of how generously the other is configured: the operating system’s own per-process hard limit, and NGINX’s own worker_rlimit_nofile directive, which requests a specific ceiling from the OS on NGINX’s behalf but cannot exceed whatever the OS itself is willing to grant.
# In the main NGINX configuration context, outside any http/server block
worker_rlimit_nofile 65535;
Setting this directive alone accomplishes nothing if the underlying operating-system limit — configured through /etc/security/limits.conf for traditional process-level limits, or through systemd’s own service-unit-level LimitNOFILE directive when NGINX runs as a systemd service, which on modern distributions frequently overrides the traditional limits.conf mechanism entirely without administrators realizing it — remains lower than what NGINX is now requesting:
# /etc/security/limits.conf
nginx soft nofile 65535
nginx hard nofile 65535
# systemd override, frequently the actual controlling limit on modern distributions
# via systemctl edit nginx.service
[Service]
LimitNOFILE=65535
Confirming which limit actually governs a running NGINX worker in practice, rather than guessing from configuration files that may or may not have taken effect, means checking the live process directly:
cat /proc/<worker_pid>/limits
A separate but closely related setting, worker_connections inside the events block, sets the maximum simultaneous connections a single worker process will accept — a value that, if set higher than what the actual, real file-descriptor limit can support, produces the misleading appearance of hitting a connection-count ceiling when the true, underlying constraint is the OS-level file descriptor limit rather than anything NGINX-specific:
events {
    worker_connections 4096;
}
The correct relationship to maintain between these two settings is that worker_rlimit_nofile should be set to at least double worker_connections, covering client connections, upstream connections, and open log files simultaneously without running the process directly up against the ceiling under normal, non-degraded operating conditions — a margin that becomes especially important under the proxy-mode doubling effect already described.
A slow-upstream cascade is the specific failure pattern that most often drives a healthy server into this ceiling under real production load, rather than steady-state traffic simply outgrowing a previously-adequate limit over time. When one backend in a load-balanced pool becomes slow rather than fully down, NGINX workers hold connections open for the full duration of the slow response rather than failing fast, consuming worker-connection slots for far longer than a healthy response would require; as those slots fill, new requests cannot be forwarded to any backend at all, remaining traffic concentrates onto whichever backends are still responding at a normal speed, those backends in turn become overloaded and slow down themselves, and eventually every backend in the pool degrades in sequence while NGINX’s own master process remains alive and outwardly healthy throughout the entire cascade — a pattern distinguishable from simple traffic growth by its specific sequence: upstream response latency visibly rises first, active connection counts climb second as a direct consequence, and only then do 502 and 504 errors begin appearing as the final, visible symptom of a problem that actually started several steps earlier.
Buffer errors, upstream sent too big header, and proxy buffer tuning
A distinct family of errors arises specifically from the buffers NGINX allocates to hold data in transit between a client and an upstream server — buffers that are separate in purpose and configuration from the header buffers covered earlier in the 400, 414, and 431 sections, and that fail in their own characteristic way when a backend produces a response larger than the space NGINX allocated to receive it.
The specific, unambiguous log signature:
upstream sent too big header while reading response header from upstream
This occurs when a backend response includes an unusually large set of headers — often accumulated cookies, extensive custom headers, or a verbose CORS configuration setting dozens of individual header lines — that exceeds NGINX’s proxy_buffer_size, the buffer specifically allocated for response headers as distinct from the response body. The fix raises the relevant buffer directives:
proxy_buffer_size 16k;
proxy_buffers 4 16k;
proxy_busy_buffers_size 32k;
proxy_buffer_size governs the first buffer, used specifically for the response headers. proxy_buffers governs the number and size of additional buffers used for the response body once the headers have been read. proxy_busy_buffers_size limits how much of that combined buffer space can be tied up sending data to the client at any one moment while more of the response is still being read from the upstream, preventing a single very slow client from monopolizing buffer memory that other concurrent requests also need access to.
A related but functionally distinct performance issue — not producing an outright error at all, but a silent, hard-to-diagnose slowdown — arises when a response body exceeds the combined proxy_buffers allocation entirely. When this happens, NGINX writes the overflow to a temporary file on disk under proxy_temp_path and reads it back from there rather than continuing to hold the growing response in memory, a spill-to-disk mechanism that only ever gets logged at NGINX’s debug verbosity level and is therefore effectively invisible during normal production operation at standard log levels. The diagnostic signature for this specific, silent problem is a request where $request_time in the access log runs many times larger than $upstream_response_time for the exact same request, even though the upstream itself logged a fast, unremarkable response time — the delay isn’t happening in the application or the network at all; it’s happening entirely inside NGINX’s own buffer-to-disk handling, invisible unless you specifically know to compare those two timing fields against each other for exactly this discrepancy.
Disabling buffering entirely for a specific location is occasionally the correct fix rather than simply enlarging the buffers further, particularly for a proxied endpoint that streams data incrementally — a chat application, a long-polling connection, or a server-sent-events feed — where NGINX’s default behavior of accumulating a complete response before forwarding any of it to the client actively works against the endpoint’s intended streaming behavior:
location /stream/ {
    proxy_buffering off;
    proxy_pass http://backend;
}
proxy_buffering off trades memory efficiency and protection against a slow client for immediate, low-latency forwarding of each chunk of data as it arrives from the upstream — the correct trade for a small number of specifically streaming endpoints, and actively the wrong default to apply broadly across an entire site, since it removes NGINX’s ability to protect a slow backend from a slow client by decoupling the two connections from each other.
The error_page directive and building error pages that actually help users
Beyond diagnosing and fixing the underlying causes covered so far, NGINX’s error_page directive controls what a user actually sees when an error does occur despite every prevention effort — and a poorly configured error page turns a routine, momentary failure into a needlessly confusing and unhelpful dead end for the person who happened to encounter it.
The basic mechanism maps one or more status codes to a specific URI, served through an internal redirect that never generates a separate, externally-visible HTTP request of its own:
error_page 404 /errors/404.html;
error_page 500 502 503 504 /errors/500.html;
error_page 403 /errors/403.html;

location ^~ /errors/ {
    internal;
    root /var/www/your-domain/public_html;
}
The internal directive on the error-serving location is not optional in any well-designed configuration — without it, the error pages themselves become directly, publicly requestable URLs in their own right, which is both a minor information-disclosure surface and simply poor design, since an error page is meant to be shown only as the result of a genuine error condition, never as a page a user or a search engine crawler navigates to intentionally.
A critical distinction determines whether a custom error page NGINX has configured actually gets shown to the client at all: by default, NGINX only substitutes its own configured error page when it cannot connect to the upstream at all — a timeout, a connection refusal, an unreachable backend. If the upstream is reachable and responds with its own error status directly — a PHP application returning a 500 of its own accord, for instance — NGINX passes that upstream-generated error page straight through unmodified, and the carefully designed custom NGINX-level error page never actually gets shown for that specific failure. Overriding this default behavior requires the intercept directives covered earlier:
proxy_intercept_errors on;
fastcgi_intercept_errors on;
With interception enabled, NGINX’s own configured error pages take over consistently for any qualifying status code, regardless of whether the upstream was reachable or not — the correct choice for a polished, consistent public-facing user experience, but the wrong choice during active development or debugging, since it discards whatever detailed error output the backend application itself may have deliberately produced to aid exactly that debugging effort.
An effective error page for a genuinely public-facing production site includes several concrete, specific elements rather than a bare, generic “something went wrong” message that leaves the visitor with nowhere useful to go next: a clearly displayed error code alongside a short, honest, non-technical explanation of what happened; visual and navigational consistency with the rest of the site, including its logo, its color scheme, and its primary navigation menu, so the page still feels like an intentional part of the site rather than an unstyled default; and concrete, actionable next steps — a prominent link back to the homepage, a working search box, or links to a small set of genuinely popular destination pages — rather than leaving the visitor at an isolated dead end with no way forward except hitting the browser’s back button.
A frequently overlooked design consideration specifically for a maintenance-mode 503: including a machine-readable Retry-After header alongside the human-readable page matters not just for well-behaved automated clients but specifically for search engine crawlers, which treat a properly configured, time-bounded 503 as an explicit and legitimate signal to preserve the page’s existing search index ranking through a brief, clearly time-limited outage — while an unexplained, sustained pattern of 503s with no such signal risks the page being gradually dropped from the index entirely, on the reasonable assumption that the content is simply gone rather than temporarily unavailable:
location = /maintenance.html {
    add_header Retry-After 3600 always;
    return 503;
}
Load balancers, upstream blocks and passive health checks
When NGINX distributes traffic across more than one backend server, an entirely new category of error and misconfiguration becomes possible — one that does not exist at all in a single-backend deployment, because there is no meaningful concept of one backend being unhealthy relative to its siblings when there are no siblings to compare it against.
The upstream block defines the pool of backend servers NGINX can route to, along with per-server parameters governing how failures against that specific server are detected and handled:
upstream backend {
    server 192.168.1.10:3000 weight=5 max_fails=3 fail_timeout=30s;
    server 192.168.1.11:3000 weight=5 max_fails=3 fail_timeout=30s;
    server 192.168.1.12:3000 backup;

    keepalive 32;
    keepalive_requests 1000;
    keepalive_timeout 60s;
}
max_fails and fail_timeout together implement NGINX’s built-in passive health checking — after max_fails consecutive failed attempts against a specific server, NGINX marks that server as temporarily unavailable and stops routing new requests to it for the duration of fail_timeout, after which it cautiously attempts to route traffic to it again to check whether it has recovered.
The default values for these two directives — one failure, and a ten-second timeout — are aggressive enough that a single, brief, transient failure removes a healthy backend from rotation for a full ten seconds, an outcome that is entirely appropriate on a genuinely unreliable network prone to real, repeated failures, but actively counterproductive on a stable network where an occasional, isolated blip is expected background noise rather than a meaningful signal of an actual problem. Raising max_fails to something like 3 gives a backend server the benefit of the doubt through a few isolated, non-repeating failures before NGINX concludes it is genuinely unhealthy and removes it from the pool — a straightforward, low-risk tuning change worth making on any production upstream block that has never had its defaults revisited. Setting the value too high in the opposite direction, however, delays the removal of a server that is genuinely failing, meaning client requests continue being routed to a broken backend for longer than necessary before NGINX finally acts on the pattern — the correct value balances tolerance for transient noise against the speed of genuine failure detection, and that balance depends on the specific network’s actual observed reliability rather than any single universally correct default.
A backup server, as shown in the third line of the example above, only ever receives traffic when every non-backup server in the pool has simultaneously been marked as failed — a useful pattern for maintaining a smaller, cheaper, or lower-capacity standby capable of keeping the site minimally functional during a genuine, complete outage of the primary pool, but not a substitute for adequate primary capacity, since it is deliberately never used at all under any normal, healthy operating condition.
Open-source NGINX — as distinct from the commercial NGINX Plus product, which adds active health checks and dynamic, reload-free reconfiguration as licensed features — cannot dynamically drain a backend server out of rotation without a full configuration reload. If a specific backend needs to be taken out of service deliberately for planned maintenance, the practical approach with open-source NGINX is either removing that server’s line from the upstream block entirely and reloading, or setting its weight to zero, in either case followed by:
nginx -t && nginx -s reload
A reload, unlike a full restart, is designed specifically to be graceful: existing, already-established connections continue to be served by the outgoing worker processes exactly as before, while new incoming connections are routed to freshly-started workers running the newly reloaded configuration — the correct, low-disruption operational pattern for applying nearly any configuration change to a live, already-running production server, and one that should be reached for far more often in practice than a full service restart, which unnecessarily drops every currently active connection rather than letting them complete gracefully.
A keepalive connection pool configured within the upstream block, as shown in the example above, allows NGINX to reuse existing already-established TCP connections to backend servers across multiple requests rather than opening a brand-new connection for every single one — reducing both the connection-establishment latency added to each request and the overall file-descriptor pressure discussed earlier, since a smaller, well-tuned pool of persistent connections replaces a much larger volume of constantly opened and closed short-lived ones. An undersized keepalive pool relative to actual sustained concurrency causes excessive connection churn as NGINX repeatedly closes and reopens connections to keep up with demand; an oversized pool wastes idle connection slots and file descriptors that sit open and unused, providing no benefit while still consuming the same finite resource — sizing this value correctly requires matching it against the application’s genuinely observed concurrent request volume rather than an arbitrary round number picked without reference to real traffic.
Business impact of unresolved server errors by sector
The specific consequences of an unresolved server error scale sharply with the type of business behind the affected site, and understanding those differences helps set the right priority and urgency for fixing a given error class rather than treating every 5xx spike identically regardless of context.
For e-commerce, a 502 or 504 occurring specifically during a checkout flow is categorically more damaging than the identical error occurring on a product-browsing page, because the checkout flow is the single narrowest point in the entire customer journey where the business actually converts a visitor’s interest into completed revenue — an abandoned cart triggered by a server error at that exact moment represents not just one lost sale but frequently a lost customer relationship entirely, since a meaningful share of shoppers who hit a payment error during checkout simply do not return afterward to attempt the purchase a second time. Cart and session-related 400 errors caused by oversized cookies deserve particular, specific attention on e-commerce platforms, precisely because shopping-cart and session-tracking cookies are exactly the pattern most likely to accumulate toward the buffer limits covered earlier in this article, and the failure surfaces at the worst conceivable point in the entire customer journey — the moment of actually attempting to pay.
For software-as-a-service and API-first businesses, a 429 rate-limiting response that lacks a proper Retry-After header, or a 401 versus 403 distinction that an API consumer’s integration code has not correctly handled, produces broken third-party integrations that can silently fail for hours or days before anyone on either side notices the actual root cause — API consumers frequently build automated retry logic around the specific status codes they expect a given service to return, and any drift from documented, consistent behavior breaks that logic in ways that are genuinely hard for the API’s own operators to detect from server-side metrics alone, since the failure manifests entirely inside a third-party client the operator has no direct visibility into.
For media and publishing sites, a sustained pattern of unexplained 503 or 504 errors correlates directly and measurably with search-engine ranking degradation, since crawlers interpret sustained server unavailability as a meaningful signal about overall site reliability and can reduce crawl frequency or, in more severe and prolonged cases, actively deprioritize previously well-ranked pages in search results — recovery once this reputational damage has occurred with a search engine’s crawling infrastructure often takes measurably longer than the technical fix that resolved the original underlying server issue, since regaining lost crawl trust runs on a substantially slower timeline than fixing a misconfigured directive.
For internal enterprise tools and B2B platforms, a 403 stemming from an overlooked SELinux policy or an expired internal client certificate, of the kind covered in the earlier sections on 403 and 495, can quietly block an entire department’s workflow for hours before anyone escalates it as an actual incident — internal tools frequently lack the same dedicated, always-watching monitoring coverage that public-facing customer traffic receives by default, meaning the error can persist invisibly until enough individual employees separately notice and report the same problem before it registers as a genuine, prioritized incident rather than a series of isolated one-off complaints.
Financial and healthcare platforms bound by regulatory compliance requirements face a distinct category of risk layered entirely separately from immediate user-facing impact: an audit trail that shows a pattern of unresolved 500-series errors touching payment-processing or protected-health-information endpoints can itself become a compliance finding in its own right during a subsequent regulatory review, entirely independent of whether any actual customer or patient was harmed by a given individual incident — the sustained, documented pattern of unaddressed errors is treated by auditors as evidence of inadequate operational controls in itself, regardless of the underlying incidents’ individual severity.
Business impact of major NGINX error categories by affected sector
| Error pattern | E-commerce | SaaS / API | Media / publishing | Enterprise internal |
|---|---|---|---|---|
| 502 / 504 during a critical transaction | Abandoned carts, lost customer relationships | Broken integrations, silent client-side failures | Reader drop-off, ad-revenue loss | Blocked workflows, escalating support tickets |
| 400 from oversized cookies or headers | Checkout failures at the point of payment | Broken authenticated sessions | Login failures for registered readers | Blocked access to internal dashboards |
| Sustained, unexplained 503 / 504 | Reduced conversion, cart abandonment | SLA breaches, contractual penalties | Search ranking degradation | Productivity loss across affected teams |
| 403 from SELinux or expired certificates | Blocked payment-gateway callbacks | Blocked partner API access | Blocked content-management access | Blocked department-wide access |
The table is a lens for prioritization under real incident pressure, not a claim that any specific error is universally more urgent than another in the abstract — the correct answer to “how urgently does this need fixing” always depends on which specific business function the affected endpoint actually serves, not on the raw status-code number alone.
A systematic troubleshooting sequence any team can follow
Given the number of distinct causes covered across every status code in this article, a fixed, repeatable troubleshooting sequence is more valuable in a genuine live incident than memorizing the individual fix for every single code in isolation, because the sequence itself, followed consistently, reliably narrows down which specific fix from everything above actually applies to the incident currently in progress.
Step one identifies the status class. A 4xx error means the request itself was rejected — check whether the rejection pattern is expected (a rate limit doing its job, a permission check correctly denying an unauthorized user) or unexpected (a routing regression from a recent deployment, a buffer limit a growing application has newly outgrown). A 5xx error means the server failed to handle a request it should have been able to handle — treat this with materially higher urgency by default, since it correlates far more strongly with genuine service degradation.
Step two reads the error log, not the browser. The status code visible in a browser tells you almost nothing about the actual cause; the corresponding NGINX error log line, matched against the specific signatures covered throughout this article — Connection refused, Permission denied, too large body, upstream timed out, too many open files — narrows the field of plausible causes dramatically before any configuration file gets touched at all.
Step three separates NGINX’s own layer from the upstream’s. For any 5xx error specifically, confirm whether NGINX itself generated the response or is merely relaying one from a backend, by testing whether the exact same request succeeds when sent directly to the backend, bypassing NGINX’s proxy entirely. If it succeeds directly, the fault is in NGINX’s own proxy configuration — a wrong address, an insufficient timeout, an undersized buffer. If it fails identically even when bypassing NGINX, the fault lives entirely in the backend application, and no NGINX configuration change of any kind will resolve it.
Step four checks for a resource ceiling before assuming a purely logical configuration bug. File descriptor exhaustion, worker_connections saturation, and PHP-FPM’s own worker-pool exhaustion each produce symptoms that closely resemble a straightforward misconfiguration but require an entirely different category of fix — raising a system-level limit, tuning a pool size — rather than correcting any single directive in a location block.
Step five checks for a security layer sitting invisibly between the request and the expected outcome. SELinux, a web application firewall, or a client-certificate verification requirement can each independently produce an error that looks, from the outside, identical to a straightforward application bug, and skipping this check on a system that has one of these layers enabled leads directly to “fixing” file permissions or application code that was never actually broken in the first place, while the invisible security layer keeps silently blocking the request regardless.
Step six confirms the fix with the same specific request that originally failed, not a generic or superficially similar one, since a configuration change can resolve one specific failure mode while leaving a closely adjacent one — a different endpoint, a slightly larger payload, a different client certificate — completely untouched; declaring an incident fully resolved based only on a single successful retry, without confirming the fix against the actual range of traffic that originally triggered the error, is a common and avoidable way for the same incident to reopen within hours of being marked closed.
A single test that should be run early and often throughout this entire sequence, because of how cleanly it separates NGINX-layer problems from backend-layer problems: bypassing the proxy layer entirely.
curl -v http://127.0.0.1:8080/health
If this direct request to the backend’s own port succeeds while the equivalent request through NGINX on port 80 or 443 fails, the fault is conclusively somewhere in NGINX’s own configuration. If the same failure reproduces identically even with NGINX bypassed entirely, the fault is conclusively in the backend, and continuing to search through NGINX configuration files at that point is directed effort spent in the wrong location.
Monitoring, alerting and turning access logs into an early-warning system
Every fix covered so far in this article addresses a problem that has already occurred and already, in most cases, already affected at least one real user by the time anyone starts actively troubleshooting it. A properly configured monitoring layer, built directly on the timing-aware access log format introduced earlier in this piece, catches the majority of these failure patterns building up before they escalate into a full, customer-visible outage — turning a reactive, after-the-fact fix into a genuinely proactive, before-the-fact one.
The specific log fields worth alerting on directly map to the specific failure patterns already covered throughout the article. A rising rate of 502 responses correlated against a specific single upstream server, rather than spread evenly across the entire pool, is the earliest available signal of that one server beginning to fail — catching this pattern early, before the passive health-check mechanism even trips, allows a deliberate, planned removal of that specific server from rotation rather than waiting for NGINX’s own automatic failure detection to react to a problem that has already been actively affecting a share of real user traffic in the meantime. A widening, sustained gap between $request_time and $upstream_response_time, the buffer-spill signature covered earlier in the piece, indicates NGINX’s own internal buffer handling is degrading well before it produces any outright, customer-visible error, giving a genuine early warning that a backend response payload has grown larger than the currently allocated buffer configuration comfortably accommodates.
A minimal, practical alerting configuration built directly on the access log includes a small number of specific, well-chosen conditions rather than an exhaustive, undifferentiated list covering every conceivable status code: an aggregate 5xx rate exceeding a small, low percentage of total request volume sustained continuously over several consecutive minutes, distinguishing a genuine, systemic problem from an isolated, brief blip that self-resolves before anyone would need to intervene; a $upstream_response_time value for a specific individual endpoint exceeding its own established, historically observed p99 latency baseline by a clear, meaningfully wide margin, catching a slow-query or slow-dependency regression before it fully escalates all the way to an outright 504; and a 403 rate spike specifically confined to a single, particular endpoint rather than distributed evenly across the entire site, which, as covered in the earlier security-layer discussion, often indicates a newly introduced access-control regression from a recent deployment rather than any actual, coordinated external attack traffic.
Centralized log aggregation — shipping NGINX’s access and error logs into a tool such as the ELK stack, Grafana Loki, or a comparable hosted log-aggregation platform — becomes genuinely necessary rather than merely convenient the moment a deployment grows past a single NGINX instance. A load-balanced deployment spreading traffic across multiple NGINX instances means a single incident’s log evidence can be scattered thinly across several separate hosts, and manually tail-ing individual log files on each host one at a time, in sequence, during an active, time-pressured incident wastes exactly the kind of time a genuine outage cannot afford to lose.
Structured JSON logging is worth adopting specifically once log volume and instance count both grow enough that plain-text log parsing with grep and awk genuinely becomes an operational bottleneck in its own right, rather than a default worth reaching for on a small, single-instance deployment where those simple, familiar tools remain perfectly adequate:
log_format json_combined escape=json
    '{'
    '"time": "$time_iso8601",'
    '"remote_addr": "$remote_addr",'
    '"request": "$request",'
    '"status": $status,'
    '"request_time": $request_time,'
    '"upstream_response_time": "$upstream_response_time",'
    '"upstream_status": "$upstream_status"'
    '}';
The single most valuable habit any team running NGINX in production can build is establishing a genuine, historically observed baseline for each of these metrics during ordinary, healthy operating conditions before an incident ever occurs, rather than attempting to judge whether a given number is normal or abnormal in the middle of an active, time-pressured incident with no prior reference point at all. A $upstream_response_time of eight hundred milliseconds is either a completely unremarkable, routine value or an active, five-alarm emergency entirely depending on whether the endpoint in question has historically, reliably responded in eighty milliseconds or in eight hundred — and that essential context has to already exist, established well in advance, before the moment an incident begins, because there is no reliable way to construct it retroactively once the pressure of an active outage is already underway.
Security-relevant errors, WAF interactions and the codes attackers watch for
A meaningful share of the errors covered throughout this article carry security implications well beyond their immediate, surface-level functional impact, and a small number of specific status-code patterns deserve particular, deliberate attention from a security perspective rather than being treated purely as routine operational nuisances to be tuned away and forgotten.
A sustained, elevated rate of 404 responses, especially when the specific requested paths follow recognizable patterns — /wp-admin/, /.env, /.git/config, /phpmyadmin/ — is the standard, well-documented signature of automated vulnerability scanning rather than genuine, organic broken-link traffic from real human visitors. These specific paths correspond to commonly misconfigured or improperly exposed files and well-known administrative interfaces that automated scanning tools systematically probe for across enormous swaths of the internet, entirely independent of whether the specific target site in question actually uses any of the corresponding software at all. A high, sustained volume of these specific 404s is not, by itself, an active security incident in progress — it is continuous, ambient background noise that essentially every publicly reachable site on the internet receives around the clock — but a sudden, sharp shift in this pattern, such as scanning traffic that begins probing a specific, previously undisclosed internal path that only appeared in a genuinely private, unpublished configuration file, warrants closer, more deliberate investigation into how that specific path detail could plausibly have leaked or become discoverable.
A cluster of 403 responses that correlates precisely with a web application firewall’s own audit log, rather than with NGINX’s standard filesystem-permission-related error log entries, confirms active WAF rule matching is genuinely occurring — worth actively monitoring for both false positives, where the WAF is incorrectly blocking entirely legitimate traffic and needs its rule tuning adjusted, and for genuine attack attempts, where a clear pattern of blocked requests reveals specifically what an attacker is actively attempting against the site, information that itself carries clear defensive value beyond the immediate, individual block.
The three SSL-specific codes covered earlier in this article — 495, 496, and 497 — deserve specific attention in any security review precisely because they are so rarely monitored by teams in general, and their scarcity in most dashboards makes them an easy, overlooked blind spot. A sudden, unexplained spike in 496 responses — missing client certificates on an endpoint that genuinely requires mutual TLS authentication — can indicate either an entirely benign client-side misconfiguration issue on a legitimate partner’s end, or, in a more concerning scenario, active reconnaissance probing specifically to determine whether a given mTLS-protected endpoint can be reached at all without presenting valid credentials, mapping out the boundary of what’s accessible before attempting a more targeted approach.
429 responses, as already established earlier in this article, generally represent rate limiting successfully doing its intended job — but the specific pattern behind a 429 spike still deserves closer scrutiny before being dismissed as routine, expected traffic. A rate limit being tripped by a single identifiable IP address is a genuinely different, and generally far less concerning, situation than the same rate limit being tripped simultaneously by hundreds of different IP addresses distributed across many separate networks, all targeting the identical specific endpoint within a similar, tightly clustered time window — the latter, much more coordinated pattern is a recognizable signature of a distributed credential-stuffing attack or a broader distributed denial-of-service attempt, and correctly recognizing and distinguishing this specific pattern is precisely why rate-limiting logs deserve genuine, ongoing security review rather than being treated purely as a capacity-management or performance-tuning concern in isolation.
Server-side request forgery deserves specific mention here because it interacts directly and dangerously with proxy_pass misconfigurations covered earlier in the 404 sections of this article. An application that constructs any part of a proxied backend URL from unvalidated, attacker-influenced user input — rather than from a fixed, hardcoded, or properly validated and allow-listed set of possible destinations — can be manipulated by a sufficiently motivated attacker into having NGINX itself proxy requests toward internal, otherwise unreachable services that were never intended to be exposed to the outside world at all, an entirely distinct and considerably more serious category of risk than any of the purely availability-focused errors covered in the rest of this article, and one that calls for careful, deliberate input validation at the application layer rather than any NGINX configuration change whatsoever, since NGINX itself is functioning exactly as configured and simply forwarding the request precisely as instructed.
Common misconfigurations that create errors nobody asked for
A specific, recurring set of configuration mistakes reliably produces errors that have nothing whatsoever to do with genuine traffic patterns, real backend failures, or any external factor at all — errors that a team introduces entirely on its own, unintentionally, through the configuration itself, and that a careful, structured configuration review would have caught and prevented before any of them ever reached production traffic in the first place.
Duplicate or conflicting location blocks are a persistent, recurring source of genuinely inexplicable routing behavior, since NGINX’s own location-matching precedence rules — exact matches taking priority first, then the longest matching prefix among the remaining candidates, then regex matches evaluated in the specific order they happen to appear in the configuration file — are frequently misunderstood even by teams that have run NGINX in production for years, and two overlapping location blocks can silently shadow one another in ways that produce a 404 for a URL that, on a quick visual read of the configuration file, appears to clearly and unambiguously have a matching, correctly written block.
Copy-pasted configuration blocks that were never fully adapted to their new context are another persistent, recurring source: a proxy_pass directive copied wholesale from one service’s location block to a newly added second service’s block, with only the surface-level server_name updated and the actual backend address left completely unchanged, silently sends every request intended for the second, newly added service to the first service’s backend instead — producing either an outright 404 if the paths genuinely happen to differ enough for the mismatch to become visible, or, considerably worse and harder to detect, a misleadingly “successful” 200 response that quietly serves entirely the wrong service’s content to the user with no error at all to flag that anything has gone wrong.
An if directive used inside a location block for anything beyond a small handful of narrowly scoped, well-understood, officially documented use cases is a well-known and specifically documented source of surprising, non-obvious behavior — NGINX’s own official documentation contains a section titled, with deliberate and pointed emphasis, “If Is Evil,” describing in specific detail how if interacts unpredictably with directives such as try_files and rewrite in ways that frequently defeat the administrator’s actual original intent while still appearing, on casual visual inspection, to be entirely reasonable, straightforward configuration. The specific, well-documented trap: adding a conditional header inside an if block that sits above a try_files directive in the same location block can silently prevent that try_files directive from ever actually being evaluated at all, producing a 404 for a file that genuinely exists on disk and genuinely would have been found successfully, had the if block simply not been present.
Configuration changes deployed without first running nginx -t account for a startling share of production outages that have absolutely nothing to do with any of the deeper diagnostic material covered throughout the rest of this article — a syntax error introduced in a hastily edited configuration file, if deployed with a full systemctl restart nginx rather than a graceful reload, is capable of taking the entire server down completely, rather than merely producing an isolated error on one specific location. nginx -t validates configuration syntax and catches the overwhelming majority of these specific mistakes before they are ever actually applied to a live, running server — running this validation check is a five-second habit that prevents a genuinely embarrassing, entirely self-inflicted, and completely avoidable category of outage:
nginx -t && systemctl reload nginx
Forgetting to reload NGINX at all after making a configuration change is a more mundane but still surprisingly common mistake, producing the specific and genuinely confusing symptom of a fix that was written correctly, appears entirely correct on repeated visual review of the file, and simply never takes effect at all in the live, running server — because the previous, unmodified configuration is, in fact, still the one actually governing every request being served, right up until an explicit reload command is issued to apply the new one.
Environment drift between staging and production — a client_max_body_size correctly raised in staging during testing but never actually applied to the corresponding production configuration, an upstream block in production still pointing at a backend server address that was decommissioned weeks or months ago, a TLS certificate that was correctly renewed in one environment but never propagated to the other — accounts for a substantial share of “this worked perfectly fine in staging” incidents, and the durable, structural fix is managing NGINX configuration through version control and a genuinely automated deployment pipeline rather than through manual, ad hoc, per-server edits applied by hand to each environment independently and separately over time.
Testing, staging and the discipline that prevents most of these errors
The overwhelming majority of the errors and specific failure modes documented throughout this entire article are preventable before they ever reach a single real production user, through a disciplined, consistently applied testing and validation process — a fact worth stating plainly and directly, because a large share of the troubleshooting guidance covered in the preceding sections exists specifically because that discipline was, for one avoidable reason or another, skipped somewhere earlier along the way.
Configuration syntax validation through nginx -t should run as an automatic, non-negotiable, non-bypassable step in any deployment pipeline before a single configuration file change is ever applied to a live server, rather than being treated as an optional manual step that an individual engineer might reasonably remember to run under normal circumstances but is equally likely to forget entirely during a rushed, time-pressured emergency change made under active incident pressure — precisely the exact moment when a syntax error is simultaneously most likely to be introduced and least likely to be caught through any careful, considered manual review.
Load testing that specifically and deliberately exercises the failure modes documented throughout this article, rather than only exercising a site’s routine, everyday happy-path traffic patterns, catches an entire category of problem well before real, paying customers ever have the opportunity to encounter it. Deliberately sending a request with a payload that specifically exceeds the currently configured client_max_body_size limit confirms the resulting 413 is handled gracefully and returns a genuinely useful, actionable error to the client, rather than being belatedly discovered for the very first time when an actual real customer attempts a legitimately large upload and hits the exact same wall in production. Deliberately simulating a slow backend response — through an artificial, intentional delay deliberately introduced somewhere in a staging environment specifically for this purpose — confirms that the currently configured proxy timeout values behave as genuinely expected under those conditions, and, critically, that the phantom-worker problem covered in detail earlier in this article does not silently and invisibly compound and worsen under any kind of sustained, realistic load.
Canary deployments and staged, incremental rollouts, where a small, deliberately limited percentage of real production traffic is routed to a newly updated configuration or application version before the change is more broadly and fully rolled out to the entire user base, catch a meaningful share of 502 and 504 regressions specifically because a newly introduced, previously untested code path frequently behaves in ways that were never actually exercised at all during standard local development or ordinary staging-environment testing — a database migration that runs correctly and completes quickly against staging’s much smaller test dataset, for instance, but takes measurably, sometimes dramatically longer against production’s genuinely much larger dataset, is a common and recurring pattern that a staged, incremental rollout with real user traffic reliably catches well before the change reaches every single user simultaneously, in a way that a purely synthetic staging-environment test, built against artificial or scaled-down data, frequently and reliably fails to catch at all.
Chaos engineering practices — deliberately, intentionally killing a specific backend process, deliberately introducing artificial network latency, deliberately exhausting a configured resource limit under a fully controlled, monitored testing condition — surface exactly the specific failure modes this entire article has worked through, but do so on a team’s own carefully chosen and controlled schedule, deliberately, rather than at whatever arbitrary and inconvenient moment production traffic first happens to trigger the same exact condition unexpectedly and without warning. A team that has already deliberately watched, in a fully controlled test environment, precisely what a 502 cascade actually looks like when one specific backend server is killed under sustained, realistic load recognizes the exact same pattern immediately and with genuine confidence when it begins to appear for real, in production — rather than needing to work through the entire diagnostic sequence completely from first principles, under genuine incident pressure, for the very first time.
A pre-production checklist built directly and specifically from the material in this article — confirming client_max_body_size matches genuine, realistic expected upload sizes; confirming proxy_read_timeout and fastcgi_read_timeout are coordinated correctly and consistently with request_terminate_timeout on the backend; confirming worker_rlimit_nofile is set to comfortably and safely exceed worker_connections; confirming custom error pages are genuinely and correctly configured and, separately, genuinely and correctly reachable; confirming rate-limiting thresholds have been deliberately tested against realistic, genuinely expected traffic patterns rather than left entirely at their untouched, generic defaults — converts the entire, extensive body of reactive troubleshooting knowledge covered throughout this piece into a proactive, structured, repeatable process, applied consistently before every single deployment rather than reconstructed painstakingly from scratch, under genuine time pressure, during every single subsequent incident.
Open questions and where NGINX error handling is still evolving
Several genuinely open questions remain in this space, worth stating plainly rather than glossing over, because a complete and honest treatment of NGINX error handling includes acknowledging the specific, real limits of current tooling and current standardization rather than presenting an artificially tidy, fully-resolved picture of a system that, in reality, still has meaningfully rough edges.
Whether HTTP/3 and QUIC’s fundamentally different underlying transport layer will eventually require an entirely new set of NGINX-specific status codes, comparable to the SSL-specific codes 495 through 497 that HTTP/1.1 and TLS ultimately produced, is not yet settled. NGINX’s own QUIC and HTTP/3 support is still comparatively new and under genuinely active development at the time of writing, and the specific error semantics for connection-level failures that are unique to QUIC’s fundamentally different, UDP-based transport model — as distinct from the traditional, well-understood TCP-based connection failures this entire article has focused on throughout — are still actively being worked out and refined in both the underlying protocol specifications and NGINX’s own practical, real-world implementation of them.
Whether the specific default timeout values NGINX has shipped with for a very long time — sixty seconds for proxy_read_timeout chief among them — remain genuinely appropriate for a web increasingly dominated by long-lived streaming connections, real-time collaborative applications, and long-polling patterns is a legitimately open, unsettled design question rather than one with any single clearly correct universal answer. The single sixty-second default was set, historically, for a substantially different web than the one that exists today, built predominantly around comparatively short-lived, discrete request-and-response cycles rather than today’s far more common long-lived, persistent, or streaming interaction patterns, and whether NGINX’s own shipped defaults should eventually shift to reflect that meaningfully changed reality, or whether the correct, more durable answer is instead that every individual site should simply be expected to tune these specific values deliberately and explicitly for its own particular traffic pattern rather than relying on any one-size-fits-all shipped default, remains a genuinely reasonable and unresolved point of active debate within the NGINX community.
Whether machine-learning-based anomaly detection, layered directly on top of the specific access-log timing fields already covered in the earlier monitoring section of this article, will eventually catch the kind of slow, gradually building degradation patterns — a steadily rising $upstream_response_time trend line building slowly and incrementally over several weeks, well before it ever actually crosses any fixed, hardcoded alerting threshold — earlier and more reliably than the fundamentally simpler, purely threshold-based alerting rules that remain the current, dominant industry standard is a genuinely active area of ongoing tooling development, not a settled, already fully solved problem. Several commercial observability platforms already market this specific anomaly-detection capability directly, but the practical, real-world false-positive rate of these approaches against genuinely normal, organic traffic-pattern variation — a legitimate, entirely expected seasonal spike during a holiday shopping period, for instance, as opposed to a genuine, real underlying performance regression that merely happens to resemble one superficially — remains, in practice, a genuinely unresolved and actively debated question, one that varies considerably and meaningfully from one specific vendor’s implementation to the next.
How the growing and increasingly widespread adoption of service meshes — Istio, Linkerd, and comparable systems, which frequently introduce their own additional proxy layer directly alongside or in front of NGINX rather than cleanly replacing it outright — affects the specific diagnostic sequence this article has laid out is not yet fully, comprehensively documented in any single authoritative place. A request now not uncommonly passes through an entirely separate sidecar proxy before it ever reaches NGINX at all, and a failure occurring specifically at that sidecar layer can present symptoms that look, from the outside, functionally identical to several of the NGINX-specific failure modes covered at length throughout this piece, while actually requiring an entirely different, sidecar-specific diagnostic approach that current, existing documentation on this specific interaction still addresses only unevenly and incompletely across the broader ecosystem.
These open questions do not undermine the practical, concrete guidance covered throughout the rest of this article — the specific fixes and diagnostic techniques laid out here work reliably today, for the traffic patterns and infrastructure architectures that remain overwhelmingly dominant in current, real-world production deployments. They are worth naming plainly and honestly nonetheless, because a field that is presented as fully, completely settled invites a dangerously false sense of confidence, while one that is honestly and accurately described as still evolving in certain specific, identifiable respects correctly and appropriately invites the ongoing ordinary vigilance that any genuinely fast-moving area of infrastructure work legitimately deserves and requires.
Reader questions about NGINX server errors, causes and fixes
Check the first digit of the status code. A 4xx code means the request itself was malformed, unauthorized, too large, or pointed at something that doesn’t exist — the client side is the issue. A 5xx code means the server failed to handle a request that was otherwise valid — treat this with higher urgency, since it correlates with actual outages.
The default path is /var/log/nginx/error.log, but many systemd-managed installations write to journald instead. If the file is empty, check with sudo journalctl -u nginx -n 100 before assuming NGINX has stopped logging.
By default, NGINX only substitutes its own configured error page when it cannot reach the upstream at all. If the backend is reachable and returns its own error status directly, NGINX passes that response straight through unless proxy_intercept_errors on; or fastcgi_intercept_errors on; is explicitly set.
NGINX generates a 502 when it cannot get a valid response from an upstream server at all — most commonly because the backend process crashed or was never started, a socket path or address is misconfigured, or a TLS handshake to the upstream failed. The signature log line is connect() failed (111: Connection refused) while connecting to upstream.
A 502 means NGINX never got a usable connection or response from the upstream. A 504 means the connection succeeded and NGINX is still waiting for the upstream to finish responding when its configured timeout — sixty seconds by default for proxy_read_timeout — expires.
Raising the timeout can trigger the phantom worker problem: NGINX holds its own connection open longer, and if the backend is PHP-FPM, a worker that was already going to finish anyway now ties up a pool slot even longer, since PHP-FPM has no way of knowing NGINX gave up early. Under sustained load to a slow endpoint, this can exhaust the entire worker pool.
A 401 means the server doesn’t know who you are and re-authenticating might resolve it. A 403 means the server does know who you are and has decided you’re not allowed regardless — logging in again does nothing for a genuine 403.
On RHEL-family systems, SELinux enforces access control independently of standard Unix permissions and can block NGINX even when ls -l shows everything is fine. Check for a denial with sudo ausearch -m avc -ts recent before assuming a permissions bug.
Raise client_max_body_size in the http, server, or location context to a value that comfortably covers legitimate uploads. The default is 1 megabyte, which is too small for most modern applications. Confirm the backend’s own body-size limit — PHP’s post_max_size, for instance — is raised to match, since both layers must agree.
client_max_body_size governs the request body. Oversized request headers, including the Cookie header, are governed by a separate directive, large_client_header_buffers, and exceeding it produces a 400, not a 413.
Four buffers of 8 kilobytes each. The count is not additive — a single header line still has to fit inside one buffer. Raising the size per buffer, not the count, is the correct fix for a single oversized header like a large cookie.
The limit_req or limit_conn modules rejecting a request because a client exceeded a configured rate or connection limit. By default NGINX returns 503 for this instead of 429; setting limit_req_status 429; and limit_conn_status 429; gives clients the more semantically correct code.
They are NGINX’s SSL-specific codes. 497 means a plain HTTP request arrived on an HTTPS-only port. 496 means a client certificate was required but none was presented. 495 means a certificate was presented but failed verification. They’re rare in ordinary browsing but common on any site using mutual TLS or mixed HTTP/HTTPS configurations.
Almost never. It is overwhelmingly a signal relayed from an upstream application — PHP-FPM, Node.js, Python, or similar — that crashed or threw an unhandled exception. NGINX generates its own 500 only in narrow cases like internal memory allocation failures.
Check the PHP-FPM error log directly, and temporarily set fastcgi_intercept_errors off; if NGINX is configured to intercept and replace backend errors with its own generic page. Revert this before returning to production, since exposing PHP stack traces publicly is a real information-disclosure risk.
NGINX has hit an operating-system ceiling on file descriptors. Every connection — client and upstream — consumes one, and proxy mode roughly doubles demand per request. Raise worker_rlimit_nofile in NGINX’s configuration and confirm the OS-level limit, often controlled by a systemd LimitNOFILE override, is raised to match.
root appends the full request URI to the configured directory. alias replaces the matched location prefix with the configured directory instead. Using one where the other was intended is one of the most common sources of a 404 for a file that genuinely exists on disk.
Without a try_files fallback such as try_files $uri $uri/ /index.html;, NGINX looks for an actual file matching the route and finds nothing, since client-side routers like React Router handle those paths entirely in the browser rather than on the server.
Check the error log signature. “Connection refused” points to a dead or unreachable backend — a 502-track problem. “Upstream timed out … while reading response header” points to a backend that’s alive but slow to respond — a 504-track problem, and the fix belongs in the application or database layer, not in NGINX’s timeout values.
Run nginx -t to check for a configuration syntax error before assuming a crash, then check whether NGINX is writing to its expected log destination at all, since file-descriptor exhaustion can silence logging at the exact moment it’s most needed.
Author:
Jan Bielik
CEO & Founder of Webiano Digital & Marketing Agency
This article is an original analysis supported by the sources cited below
RFC 9110: HTTP Semantics The IETF standard defining core HTTP semantics, including the five status-code classes, the requirement that a 401 response include a WWW-Authenticate header, and the renaming of several status codes such as 413.
Hypertext Transfer Protocol (HTTP) Status Code Registry The authoritative IANA registry listing every officially registered HTTP status code and its class, used throughout this article to confirm which codes are standardized and which are not.
List of HTTP status codes A comprehensive reference cataloguing every standard and commonly used non-standard HTTP status code, including the 4xx and 5xx codes covered in detail in this piece.
NGINX 502 Bad Gateway: Causes and Fixes A diagnostic guide covering the seven most common causes of 502 errors in production NGINX deployments, including connection-refused signatures, socket misconfigurations, and SELinux interference.
HTTP 502 Bad Gateway: Causes & Fixes An explanation of the request chain behind a 502 response, including stale DNS resolution caching, upstream TLS certificate failures, and broken certificate chains as specific causes.
nginx 504 Gateway Time-out: causes and fixes A technical breakdown of the three-phase NGINX proxy timeout model and the specific log signatures that distinguish a connect-phase failure from a read-phase failure.
504 Gateway Timeout in NGINX: Fix It in 5 Minutes A practical guide to tuning proxy and FastCGI read timeouts across a multi-layer proxy chain, including the rule that outer-layer timeouts should exceed inner-layer timeouts.
php fpm 504 gateway timeout A detailed explanation of the phantom worker problem, where a PHP-FPM worker continues executing after NGINX has already timed out and returned a 504 to the client.
500 Internal Server Error: What It Means & How to Fix It A guide distinguishing NGINX-generated 500 errors from backend-relayed ones, including how to locate the correct PHP-FPM or PHP error log for a given failure.
Fix NGINX 500 Internal Server Error: Causes & Solutions An explanation of how fastcgi_intercept_errors changes which layer’s error output reaches the client, and when a 500 should be attributed to PHP-FPM rather than NGINX itself.
PHP-FPM Returns HTTP 500 Instead of PHP Errors? How to Display Exact Errors in Nginx A walkthrough of adjusting PHP-FPM and NGINX settings to expose detailed PHP errors during debugging, and the security reasons to revert that exposure before returning to production.
How to Fix Nginx 403 Forbidden A diagnostic guide separating the distinct causes of a 403 response, including missing index files, filesystem permissions, SELinux labels, and symlink restrictions.
How to Fix ‘403 Forbidden: directory index’ Errors in Nginx A detailed explanation of the directory-index 403 error, the role of the autoindex directive, and the specific log line that confirms the diagnosis.
How to Fix Nginx 404 Not Found A troubleshooting guide covering root and alias misconfigurations, broken try_files chains, and the distinction between an NGINX-side 404 and one relayed from a proxied backend.
Nginx Root vs Alias: Path Mapping and Troubleshooting A focused explanation of how the root and alias directives construct filesystem paths differently, and the trailing-slash mistakes that most commonly produce unexpected 404 or 403 errors.
404 Not Found Error Nginx: Causes And How to Fix It A guide covering single-page application routing failures, proxy_pass path-stripping behavior, and the try_files fallback pattern required for client-side routed applications.
Nginx client_max_body_size: Fix 413 Request Entity Too Large A configuration reference for the client_max_body_size directive, its default value, its context inheritance rules, and the security trade-off in raising it.
How to Fix 400 Bad Request: Request Header Or Cookie Too Large Nginx A diagnostic walkthrough for the oversized-cookie 400 error, including how to measure the actual header size and why large_client_header_buffers is not an additive limit.
400 Bad Request: Request Header Or Cookie Too Large in Nginx An explanation of how accumulated WordPress and WooCommerce cookies commonly trigger this error, and the server-side session storage pattern that resolves it durably.
NGINX Rate Limiting: Complete Guide with Examples A configuration guide for limit_req and limit_conn, including the default 503 status NGINX returns for rate-limited requests and how to override it to the more appropriate 429.
How To Limit Rate of Connections (Requests) in NGINX A practical walkthrough of configuring limit_req_zone and limit_conn for API endpoints, with worked configuration examples for setting the rejection status code.
497 HTTP Request Sent to HTTPS Port A reference explaining the 497 status code, its trigger condition, and the error_page-based redirect pattern for handling mismatched-protocol requests gracefully.
495 SSL Certificate Error – HTTP status code explained A technical explanation of certificate-chain verification failures behind the 495 status code, including the role of ssl_verify_depth in multi-intermediate certificate chains.
496 SSL Certificate Required – HTTP status code explained A reference distinguishing the 496 status code from 495, covering the ssl_verify_client directive’s on, optional, and optional_no_ca modes.
Nginx: Too Many Open Files – Diagnosing File Descriptor Exhaustion A technical guide to file-descriptor exhaustion in NGINX, covering worker_rlimit_nofile, the OS-level limits that can override it, and the accept4() failure signature.
Nginx: worker_connections Are Not Enough – Causes & Fixes An explanation of connection-slot exhaustion distinct from file-descriptor exhaustion, and mitigation strategies including timeout reduction and keepalive tuning.
NGINX backend cascade failure: when slow upstreams take down everything A case study describing how one degraded backend server can cascade into a full-pool failure through connection-slot exhaustion, and the passive health-check tuning that mitigates it.
Configuring Logging | NGINX Documentation NGINX’s own documentation on error_log and access_log configuration, including structured JSON logging and the upstream timing variables used throughout this article.
Best Practices for Logging and Monitoring with Nginx A practical guide to custom log formats incorporating upstream response time and connection time variables for production monitoring and alerting.
Usage Statistics and Market Share of Nginx W3Techs’ ongoing survey of NGINX’s web server market share, used to establish the scale of NGINX’s deployment across the web referenced in this article’s business-impact discussion.
| Citing this article? Brief excerpts are welcome. Please credit Webiano.digital, name the author where stated, and include a link to https://webiano.digital and to this original article. Full or substantial republication requires prior written permission. Read our Copyright and Content Use Policy. |
This article was prepared with the assistance of artificial intelligence tools. The content underwent expert human review, and Webiano Digital & Marketing Agency assumes editorial responsibility for its final version and publication.